Serialize per-Service state behind UID locks, order events per Service, and
make readiness and watcher ownership generation-aware. Coordinate shared lease
membership so cleanup cannot cancel a recreated Service, drain cluster workers
before restart, and start the shutdown watcher before slow startup calls.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
The ARP suite runs four kind clusters against one Docker daemon, so
acknowledging a leader kill regularly exceeded the 5s budget and failed
the IPv6 failover specs before any assertion ran.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Instance creation added addresses, VLAN or macvlan links and DHCP
clients incrementally, so a failure part way through left the node
holding state nobody owned. Initialization now unwinds what it created,
and link cleanup only deletes attachments this instance created that no
remaining instance still uses.
Namespace-dependent tests now skip unless KUBE_VIP_REQUIRE_NETNS is set,
which CI sets on the privileged job so lost capabilities turn it red
instead of silently skipping.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Instances were kept in a sync.Map with a per-instance mutex for the
refcount, so lookup and refcount update were not atomic: concurrent
Insert and Remove could resurrect a deleted instance or drop a live one.
Hold one manager mutex across both, and buffer link subscriptions so a
netlink sender is never parked on an unread channel during shutdown.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Sanitisation maps '-' onto the '_' separator, so "a-b/c" and "a/b-c"
shared one nftables chain, and TCP and UDP on the same port collided.
ServicePortIDs appends the protocol and, when sanitisation changed the
name or the ID grew too long, a hash of the raw name. It also returns
the previous port-only ID so existing chains can be migrated.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Netlink carries the address and route protocol in a single byte, so a
configured value above 255 was silently truncated on the wire and never
matched again on readback. Reject it during config validation instead.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Serialize the interface link cache, route tracker and address configuration so
concurrent Services cannot corrupt shared state or deadlock on nested address
locks.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Encode the instance name, address protocol and an ordered VIP list on the
Kubernetes lease so a restarting instance can tell which tagged addresses it
still owns. Only the current holder publishes the annotation.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Signed-off-by: Cellebyte <marcel.fest@live.de>
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Review follow-ups: step-level continue-on-error with a run-summary warning
instead of a silently-neutral job, ginkgo JSON report so the log artifact
is never empty, always-upload coverage with if-no-files-found=error,
read-only workflow permissions, GOMAXPROCS=4 for target consistency.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
Register the cluster handle before setup assertions so partial Kind creation can be cleaned up, while keeping teardown safe when setup fails before registration.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
shouldAddServiceIP() checks BGPAttachIPToInterface on a per-service
config struct. NewInstance() builds that struct fresh for each Service,
copying over most fields from the global config, missing this one. As
a result the flag has no effect regardless of its value, and BGP-mode
Service VIPs are never bound to the interface.
Copy the field at both construction sites where it's built, and add
a regression test covering the propagation.
Signed-off-by: Justin Cichra <jrcichra@yahoo.com>
go.mod requires go >= 1.26.4 but unit-tests-docker ran golang:1.25.6
with GOTOOLCHAIN=local and failed before running any test. Bump to
1.26.6 and stop leaving a root-owned coverage.out behind on Linux
hosts while preserving the test exit status.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
The IPv6 control-plane VIP reachability check used a 5s Eventually
window; under the 4-process parallel e2e run on a 4-vCPU runner NDP
convergence for the IPv6 VIP can exceed that, causing intermittent
timeouts while sibling specs pass. Raise it to a load-tolerant window
matching the IPv4 case; the reachability assertion is unchanged.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
Make the endpoint watcher the sole active-endpoint annotation writer so a Service snapshot captured during startup cannot replace a newer endpoint. Preserve intentionally empty snapshots across endpoint-to-zero-to-same transitions, select the cleared annotation from the configured egress family, reject malformed or wrong-family endpoints, and preserve the other family in dual-stack state.
Fixes#1673.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(endpoints): recompute and withdraw only when no longer referenced
Track EndpointSlice/Endpoints deletions in provider state instead of stopping
the watcher or clearing unconditionally. Recompute the aggregate endpoint set
after each deletion and only withdraw local routing/BGP/DNAT state once no
tracked object still references it, matching the existing behaviour for a
Modified event that reduces endpoints to zero.
Remove the now-unreachable per-mode delete()/deleteAction() hooks, which acted
on stale pre-deletion state and could withdraw prematurely while another
object still referenced the same address. Fix the WireGuard control-plane
endpoint watcher to drop deleted objects from its cache instead of reloading
them as still current.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* feat(worker): support global leader election for BGP and WireGuard
Wire the existing global leader-election machinery into BGP.StartServices and
WireGuard.StartServices so both modes can run with a single node advertising
all services, matching the option already available for ARP and RoutingTable.
WireGuard has no multipath mechanism, so it must always run some form of
leader election (per-service or global); remove its no-election path and the
redundant services watcher previously started from OnStartedLeading, which
would have run a second time alongside the global election path.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(services): drop unnecessary election guard on route teardown
route.Manager.Delete is reference-counted per route and safe to call even
when nothing is tracked for it, exactly like the existing BGP host teardown.
Remove the leader-election guard on the RoutingTable branch of deleteService
so both branches read identically and route cleanup runs consistently across
all leader-election configurations.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(endpoints): treat an unknown ready condition as ready
Deferring a nil Serving to Ready matched the Serving godoc but stopped
half way: per the EndpointConditions.Ready godoc a nil Ready is an unknown
state that consumers should interpret as ready, which is what kube-proxy
does. An endpoint with both conditions unset, common in manually managed
EndpointSlices for external workloads, was therefore skipped and never
selected as a local endpoint.
Only skip the endpoint when the resolved condition is explicitly false,
and cover the condition permutations in the provider tests.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(endpoints): reconcile fully on endpoint object deletion
Delete only mirrored part of AddOrModify's zero-endpoint handling, so a
deleted EndpointSlice left the datapath inconsistent in three ways.
In ARP global-leader mode the VIP clusters were left running with no
backends, because the cluster stop that AddOrModify performs was missing.
When endpoints remained, lastKnownGoodEndpoint was never revisited, so a
last known endpoint that lived in the deleted slice stayed stale: egress
rules were neither torn down nor moved and the active-endpoint annotations
were not refreshed. The EndpointSlice controller can delete a whole slice
during consolidation without touching the survivor, so no follow-up event
is guaranteed to repair this. In WireGuard mode processInstance never ran,
leaving DNAT rules pointing at removed addresses.
Extract the shared decisions into shouldProcessInstance and
handleNoEndpoints and use them from both paths, and run the same
lastKnownGoodEndpoint and annotation reconciliation after a deletion.
handleNoEndpoints also guards against a missing instance, which the
deletion path can legitimately hit. The getEndpoints error is now wrapped
with the provider label like every other error here.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* docs(bgp): call out the services election behaviour change
Enabling leader election in BGP mode now runs a global services leader.
Nothing in the configuration changed for existing deployments, but a user
who enabled it for the control plane previously got the no-leader path,
where every node advertised the service VIP over ECMP, and now gets a
single advertising node.
Record this in the changelog and warn once on startup when this path is
taken, pointing at the settings that restore the previous datapath.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* refactor(endpoints): deduplicate the control plane endpoint watcher
The watch.Deleted case duplicated the Added/Modified body except for the
provider mutation, which meant maintaining the log message and the DNAT
update in two places. Pick the mutation from the event type and share the
rest.
Also state the single-object invariant on the Endpoints provider's
DeleteObject, so its asymmetry with the slice provider is not mistaken for
an oversight.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(endpoints): only ever consider active endpoints
GetLocalEndpoints skipped endpoints whose conditions said they were not
serving, but GetAllEndpoints applied no filtering at all. A service using
externalTrafficPolicy: Cluster therefore advertised backends that had
already been marked as not ready, and the two policies disagreed about
which endpoints back the same service.
Extract the condition evaluation into isServing and apply it on both
paths, and assert in the tests that Cluster and Local agree.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* refactor(endpoints): reconcile every endpoint event through one path
Now that a deletion recomputes the remaining endpoints, AddOrModify and
Delete differed only in how the event mutated the provider. Keeping two
near-identical bodies is what let their behaviour drift apart in the first
place, so fold them into a single Reconcile that dispatches the mutation
in applyEvent.
Deletions consequently pick up the parts of the add path they were still
missing: the IPv6 egress guard, the leader election start, and the
endpointless opt-in branch, which now keeps an opted-in Cluster service up
after its last EndpointSlice disappears instead of tearing it down.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
---------
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
The endpoint worker's delete() path calls clear(nil, nil, service), and
clear() unconditionally dereferenced svcCtx.LeaderCancel, panicking on
every service or endpoint deletion in WireGuard mode (reached via the
endpoint watcher on a Deleted event). Guard the dereference with a nil
check on svcCtx. Adds a regression test that reproduces the panic.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(e2e/services): pass metrics address as container arg
The prometheusHTTPServer env var is never read by kube-vip; environment
parsing only knows prometheus_server and ignores empty values, so every
parallel DaemonSet still tried to bind the :2112 flag default on the
shared host network. Pass the address as --prometheusHTTPServer instead,
where an empty value really disables the metrics server.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(egress): restore CIDR fallback and cluster-wide SNAT exclusion
Auto-discovery dropped the kube-controller-manager fallback, breaking
clusters whose CNI does its own IPAM without Node PodCIDR allocation.
Fall back to the --cluster-cidr/--service-cluster-ip-range flags when
the ServiceCIDR or Node APIs yield nothing.
Per-node PodCIDR discovery combined with getSameFamilyCidr also
narrowed the SNAT exclusion to the local node's pod CIDR, so egress
traffic to pods on other nodes was SNAT'd to the VIP. Exclude every
same-family pod CIDR in both the nftables and iptables paths.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(e2e/services): fail failover tests when the VIP never recovers
leaderFailover and podFailover returned nil when the watch drained
without any post-kill update passing httpTest, so an unreachable VIP
after failover passed CI. Keep the warn-and-continue polling, but turn
the drain path into an error.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(e2e/services): require sustained quiet window in lease error check
A single quiet 2 s interval can coincide with the pause between failing
election retries and produce a false pass for the #1664 guard. Require
three consecutive intervals without counter growth and reset the streak
whenever the counter grows.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(svcs): log service deletion only when a tracked service is removed
deleteTrackedService logged '(svcs) deleted' for every watch event of
every non-LoadBalancer service, even when nothing was tracked. Move the
log inside the svcCtx guard.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(svcs): skip API refresh when egress endpoints are unchanged
updateEgressConfiguration issued a Services Get on every no-op watch
event before short-circuiting. Compare the ActiveEndpoint annotations
first and only refresh the service from the API when they differ.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(e2e/services): drop dead StartServiceTest and restore run summary
StartServiceTest was dead code once main.go inlined the phases, and the
E2E_KEEP_LOGS-conditional temp-dir cleanup plus the 'Testing Complete'
summary silently disappeared with it. Reinstate both in run() and
collect every test result so parallel failures are all reported instead
of collapsing to the errgroup's first error.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* style(e2e): gofmt test files
gofmt -l flagged e2e_bgp_healthcheck_test.go (the Mode == ModeBGP block
body was never re-indented) and a trailing space in e2e_sigusr1_test.go.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* ci: write ginkgo JSON reports where the artifact upload finds them
Without --output-dir ginkgo resolves the report path relative to the
suite directory, so /tmp/kube-vip-test-report-*.json landed under
testing/e2e/tmp/ and the /tmp/kube-vip-test* artifact glob missed it.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* ci: scope cancel-in-progress to PRs and restore tag builds
cancel-in-progress: true also cancelled in-progress main builds on
back-to-back merges; limit cancellation to pull_request runs. The
branches: [main] filter added in the refactor dropped the tag pushes
the bare push trigger previously covered, and the release workflow
only publishes images, so restore lint/test coverage for v* tags.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* ci: fail the validation job on unformatted Go code
make check only formats '*.go pkg cmd' and merely warns, which let
unformatted files under testing/ land. Add a blocking gofmt -l check
over the whole repo that prints the offending files.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(e2e/services): kill kube-vip pods in the test namespace during failover
Since the parallel-phase refactor the kube-vip DaemonSet runs in the
per-test namespace, but the failover killer still listed pods in
kube-system, so it never deleted a single pod and no failover was ever
induced. The lenient drain path masked this; the strict assertion
exposed it.
Target the test namespace, gate success on events observed after at
least one actual pod kill, extend the watch window to 60s to leave
convergence margin after the ~25s kill churn, and return distinct
errors for aborted watch, zero kills, and unreachable VIP. Detach test
cleanup from the errgroup context (context.WithoutCancel) and demote
cleanup-path Fatals to errors so one failing test no longer kills
sibling teardown.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(e2e/bgp): raise route-destination timeout for parallel runs
With ginkgo --procs=4, sibling processes create kind clusters and load
images on the same runner; the 30s window for the first route check
overlaps that contention and flakes (observed >13s convergence even in
passing specs). Use 120s, matching the BGP health-check suite's
re-announcement timeout. Eventually returns on success, so passing
specs are unaffected.
Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
---------
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
Co-authored-by: Claude Fable 5 <noreply@anthropic.com>
Use one control-plane node for basic route checks and three for health-check scenarios so stopping one API server preserves quorum. Four Ginkgo workers now peak at eight control-plane containers instead of twelve.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Scope each egress DaemonSet to its test namespace, pin Kind's dual-stack Pod CIDRs, retain per-instance nftables tables, and grant the test service account ServiceCIDR discovery access.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Read ServiceCIDRs and Node PodCIDRs through the Processor client, retain a Service-only controller-manager fallback, and grant generated ClusterRoles get/list/watch access to ServiceCIDRs.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Base teardown on tracked UID state so LoadBalancer-to-ClusterIP transitions cancel the service context and remove the active instance even when the new object is ignored.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Run ARP, routing-table, and BGP modes on separate runners, shard scenario resources by Ginkgo worker, and cap routing-table mode at two workers for Kind stability.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Run independent service scenarios in dedicated namespaces, add per-namespace RBAC and cleanup barriers, make goroutine cleanup cancellation-safe, and parameterize CI execution with phase timing.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
Replace fixed waits with polling, remove obsolete serialization, and align the BGP health-check mode guard with the rest of the BGP suite.
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* refactor(errors): centralize fatal error handling
Detect wrapped PanicError values consistently and preserve their underlying causes when adding fatal context. Apply the helpers to manager, cluster, and IPVS error paths.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(watchers): restart after terminal watch failures
Propagate fatal endpoint watcher failures through the owning service watcher so kube-vip releases leadership instead of remaining active with a stale watch. Treat terminal service, node, and annotation watch failures as errors while preserving clean context cancellation.
Return exhausted authorization failures to RetryWatcher, safely decode watch error objects, and replace direct go-spew diagnostics with structured logging.
Fixes#1685
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(services): replace state after traffic policy changes
Recreate the service context and instance as one generation when a Service change requires teardown. Ignore delayed leadership cleanup from superseded contexts so it cannot remove replacement state.
This prevents a stale Cluster-policy endpoint watcher from winning the service lease after externalTrafficPolicy changes to Local.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(cli): return command errors to container runtime
Propagate manager and service command failures through Cobra so the process exits with status 1. Show usage for invocation errors while keeping runtime failures concise.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* refactor(logging): use structured errors
Replace direct stdout error output with slog records for command failures and traffic mirror qdisc lookup failures.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
* fix(watchers): continue after endpoint deletion
Keep EndpointSlice watchers active when an individual endpoint object is deleted so replacement objects can be observed and service traffic can recover.
Assisted-by: GitHub-Copilot:unspecified
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
---------
Signed-off-by: Marcel Fest <marcel.fest@telekom.de>
kube-vip's DHCP client uses nclient4, whose BroadcastRawUDPConn.ReadFrom could
compute a negative DHCP length and panic on a malformed reply. That was fixed
in insomniacslk/dhcp#583; this bumps the module past that commit.
Signed-off-by: thc1006 <84045975+thc1006@users.noreply.github.com>
the connmark policy-based routing was broken by tailscale, as we collide
with their connmark range (bits 16 to 23)
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
The star history chart in the README was broken because it relied on a data source that is now restricted by GitHub's stargazer API limits. Point the chart and its link to an alternative provider that uses a different data source requiring no API token, so the chart renders correctly again.
This PR adds an explicit configuration option `vip_skipdad`. This allows
for a proper behaviour in IPv6 networks with RT mode and ECMP. Without
this option only one node can ever hold the same IPv6 VIP what defeats
the purpose of ECMP.
While the ARP mode currently has a recovery mode for failed DAD, RT mode
misses it. It is also more feasible to use config option, as recovery
mode in RT mode would always introduce a ~5s blackholing (we know there
will be a conflict, so first attempt to add a VIP will fail and only the
next one will force IFA_F_NODAD).
For simplicitly we ignore IPv4/IPv6 checks, as kernel transparently
strips IFA_F_NODAD from v4 addresses without throwing errors.
For systems with IPv4 duplicate detection (called ACD and used e.g. in
RHEL10's NetworkManager) this code has no effect as it's only userspace
action and addresses we add via netlink bypass any check.
First discovered on a dual-stack cluster with two routing-table-mode
advertisers: the ingress VIP answered or timed out depending on which
ECMP path the flow hashed to; with NODAD both advertisers accept
traffic.
Signed-off-by: Mat Kowalski <mko@redhat.com>
* fix(lease): do not let a stale cleanup cancel a recreated lease
Every object that starts leader election also starts a goroutine that calls
Manager.Delete once its context is cancelled. Manager.Delete looked the lease up
by name only, so it acted on whatever lease held that name at the time it ran,
not the one the caller was given.
When a service is torn down and rebuilt straight away, the replacement lease is
already registered by the time the old cleanup goroutine runs, so the cleanup
cancels the live replacement and removes it from the manager. The service is
then never handled again: its election loop exits, the lease keeps an empty
holderIdentity, and the VIP is never re-advertised.
This is reachable from an ordinary service update. Flipping
externalTrafficPolicy makes serviceChanged cancel the service context and
rebuild it, which reproduced the stuck lease for minutes.
Pass the lease the caller owns to Manager.Delete and ignore a stale caller,
which keeps cleanup scoped to the instance it belongs to. Callers already hold
that lease. Passing nil keeps the previous behaviour of deleting whichever lease
currently holds the name, which is what the existing tests assert.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(lease): retire a lease when its service is torn down
The instance guard in Delete stops a late cleanup from cancelling a replacement
lease, but it cannot help when the replacement *is* the same instance.
A service teardown cancels the service context and leaves the lease registered,
because the cleanup that removes it is deferred to a goroutine. The rebuild that
follows calls Add, which finds that lease still in the map and hands it straight
back, so the new service context is parented to a lease the pending cleanup is
about to cancel. The service then cycles: acquire, lose, re-acquire, every few
seconds, and never settles.
Add Manager.Retire, and call it from the serviceChanged teardown next to the
svcMap purge, so the lease is out of the map before the replacement context is
built. Add also refuses to hand out a lease whose context is already cancelled,
which closes the same hazard for any other path that cancels a lease directly.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(lease): keep a common lease alive for the services still using it
Review feedback from Patryk on #1669: Retire cancelled the lease context
outright, so with a common lease a modification of one service would also tear
down every sibling sharing that lease.
Retire was only ever needed for its side effect of getting the lease out of the
map before the rebuild, and Delete already does exactly that once the last
object is gone. Drop Retire and have the teardown path call Delete with its own
object name, so siblings keep the lease alive and the manager API stays
Add/Delete/Get.
TestManager_LeaseLifetimeInvariant replaces the single-scenario test with the
rule for the whole surface: a lease stays usable for exactly as long as at least
one object holds it, and a rebuild afterwards gets a fresh one. It is table
driven over 1, 2 and 4 objects, and the 2 and 4 cases fail against the reviewed
behaviour with "lease was cancelled with N object(s) still holding it".
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(services): start the leader-election loop once per service - #1665
startLeaderElection restarts itself until the service context is cancelled,
so it only needs to be started once per service lifetime. It was started from
startServiceHandlingIfNeeded on every AddOrModify call instead, and AddOrModify
runs on every EndpointSlice event, so endpoint churn accumulated duplicate
permanent loops for the same service, all contending on the same lease.
Guard the spawn with a sync.Once on the service context. A Once needs no
clearing: the loop is bound to the service context, which is replaced whenever
the service is recreated.
Also drop the les *atomic.Int64 parameter, which was only ever incremented.
Adds a unit test that drives AddOrModify three times and asserts the loop
starts once (fails pre-fix with 3), and an -endpointFlap service e2e test that
flaps the backend 1->0->1 five times and asserts the VIP serves traffic and the
lease has a holder again.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): fault leases and API server access in the e2e test - #1665
The endpointFlap e2e test only asserted that the service recovered after
endpoint churn, which the unfixed code also satisfies, so it did not prove
anything about the reported failure.
Inject faults that actually stress the per-service leader election and assert
convergence after each one:
- endpoint churn: backend scaled 1->0->1 five times
- lease faults: the lease is deleted, then its holderIdentity is blanked, which
is the exact state reported in the issue
- API server faults: the apiserver is blocked from the leader for longer than
the lease duration, so its election client loses its backend, then restored
The assertions are on the feature contract, a held lease and a served VIP,
rather than on election internals, so they stay meaningful if the
implementation changes. Duplicate loops are not observable from outside the
process; that part stays pinned by the unit test.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): assert election faults recover, via new election metrics - #1665
The previous e2e test only asserted the service recovered, which the unfixed
code also satisfies, so it proved nothing. The duplicate election loops are not
observable from outside the process, so there was nothing to assert on.
Export the missing state as metrics, replacing the write-only les *atomic.Int64
that used to sit in startLeaderElection with real instrumentation:
- kube_vip_service_election_loops{namespace,name}: live election loops, tracked
for the lifetime of the goroutine. More than 1 per service means loops leaked.
- kube_vip_service_election_attempts_total{namespace,name}: election attempts,
so a wedged restart loop is visible as a counter that stops advancing.
- kube_vip_service_election_errors_total{namespace,name,reason}: election
failures, with reason="no_lease" for the service context and lease manager
desync.
The e2e test now injects a fault per reported failure mode and asserts a signal
that is actually broken when that bug is present:
- endpoint churn, five debounce-separated flaps (#1665): loops stay <= 1
- endpointslice deletion (#1663 / #1664): no reason="no_lease" errors
- lease deletion and blanked holderIdentity (#1650): attempts keep advancing
- apiserver blocked from the leader past the lease duration: same loss path
Every fault is also followed by the feature contract: a held lease and a VIP
that serves traffic. The unit test asserts the loop gauge alongside the call
count so both layers agree.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): assert the election error counter settles, not that it is zero
Both the fixed and the unfixed branch recorded one reason="no_lease" increment
while the service was first set up, so asserting the counter is zero failed on
correct code too. The #1664 desync makes the counter climb for the lifetime of
the process, so assert it stops growing instead.
Also sample the election loop gauge a few times rather than once, since a loop
that is about to start may not be visible in a single scrape while a leaked one
never goes away.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): assert election progress after a real leadership loss
Deleting the lease object does not make the election client lose leadership, it
just recreates the lease on the next renew, so no new election attempt follows
and the progress assertion failed on correct code.
Move that assertion to the apiserver partition, which is the fault that actually
drives OnStoppedLeading and returns the election, and is therefore where the
#1650 WaitGroup deadlock would wedge the restart loop. The lease object faults
keep asserting convergence only.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): cover the remaining election fault scenarios - #1665
The suite only faulted the paths that the three known bugs live on. Add the
neighbouring ones so a regression in this subsystem is caught wherever it lands:
- VIP release on zero endpoints: with a local traffic policy and no endpoints
anywhere, the address has to stop answering instead of black-holing traffic.
Nothing asserted the yield half of the endpoint churn cycle before.
- externalTrafficPolicy flip: makes serviceChanged cancel the service context and
drop it from svcMap, so the next event has to build a fresh context and lease.
Same desync class as the endpointslice fault, reached by a different trigger.
- service event storm: 15 annotation patches, driving the spawn-once invariant
from the service watch instead of the endpoint watch.
- follower partition: cutting a non-leader off from the apiserver must not move
the lease, stop traffic, or leak a loop on the node that comes back.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): let the election loop count settle before asserting it
A fault that rebuilds the service context, such as the externalTrafficPolicy
flip, legitimately has the old and the new loop alive at the same moment, so a
single scrape saw 2 loops on correct code.
Poll until the count settles instead. A leaked loop only exits with its service
context, which outlives the test, so it never settles and is still caught: the
unfixed code reports 11 loops after endpoint flapping.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): fault the externalTrafficPolicy teardown path
With the lease retirement fix underneath, a service that is torn down and
rebuilt by a traffic policy change converges again, so this fault can be
asserted like the others: at most one election loop, a settled error counter, a
held lease and a served VIP.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): stop the fault suite exhausting the client rate limiter
The fault tests poll the API while waiting for convergence, and by the last
fault the shared clientset had spent client-go's default 5 QPS budget, so a
lease read failed with
failed to get lease "kubevip-kube-vip-service": client rate limiter Wait
returned an error: context deadline exceeded
which looked like a convergence failure but was the test's own client giving up.
Raise QPS for the harness and halve the lease polling rate.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* test(services): fault a common lease sibling teardown
Cluster-level cover for the case Patryk raised in review of #1669: two services
share one lease, the first is deleted, and the second has to keep serving on that
same lease. A teardown that cancels the lease instead of just releasing the
leaving service takes the sibling down with it.
Adds a commonLease field to the Service helper, which sets the
kube-vip.io/serviceLease annotation along with the cluster traffic policy that a
common lease requires. Also initialises the annotation map unconditionally: it
was only allocated on the egress path, so setting any other annotation first
would have nil-panicked.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
---------
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(lease): do not let a stale cleanup cancel a recreated lease
Every object that starts leader election also starts a goroutine that calls
Manager.Delete once its context is cancelled. Manager.Delete looked the lease up
by name only, so it acted on whatever lease held that name at the time it ran,
not the one the caller was given.
When a service is torn down and rebuilt straight away, the replacement lease is
already registered by the time the old cleanup goroutine runs, so the cleanup
cancels the live replacement and removes it from the manager. The service is
then never handled again: its election loop exits, the lease keeps an empty
holderIdentity, and the VIP is never re-advertised.
This is reachable from an ordinary service update. Flipping
externalTrafficPolicy makes serviceChanged cancel the service context and
rebuild it, which reproduced the stuck lease for minutes.
Pass the lease the caller owns to Manager.Delete and ignore a stale caller,
which keeps cleanup scoped to the instance it belongs to. Callers already hold
that lease. Passing nil keeps the previous behaviour of deleting whichever lease
currently holds the name, which is what the existing tests assert.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(lease): retire a lease when its service is torn down
The instance guard in Delete stops a late cleanup from cancelling a replacement
lease, but it cannot help when the replacement *is* the same instance.
A service teardown cancels the service context and leaves the lease registered,
because the cleanup that removes it is deferred to a goroutine. The rebuild that
follows calls Add, which finds that lease still in the map and hands it straight
back, so the new service context is parented to a lease the pending cleanup is
about to cancel. The service then cycles: acquire, lose, re-acquire, every few
seconds, and never settles.
Add Manager.Retire, and call it from the serviceChanged teardown next to the
svcMap purge, so the lease is out of the map before the replacement context is
built. Add also refuses to hand out a lease whose context is already cancelled,
which closes the same hazard for any other path that cancels a lease directly.
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
* fix(lease): keep a common lease alive for the services still using it
Review feedback from Patryk on #1669: Retire cancelled the lease context
outright, so with a common lease a modification of one service would also tear
down every sibling sharing that lease.
Retire was only ever needed for its side effect of getting the lease out of the
map before the rebuild, and Delete already does exactly that once the last
object is gone. Drop Retire and have the teardown path call Delete with its own
object name, so siblings keep the lease alive and the manager API stays
Add/Delete/Get.
TestManager_LeaseLifetimeInvariant replaces the single-scenario test with the
rule for the whole surface: a lease stays usable for exactly as long as at least
one object holds it, and a rebuild afterwards gets a fresh one. It is table
driven over 1, 2 and 4 objects, and the 2 and 4 cases fail against the reviewed
behaviour with "lease was cancelled with N object(s) still holding it".
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
---------
Signed-off-by: Maximilian Rink <maximilian.rink@telekom.de>
In the RT-mode with cp_enable, health check resolves the node address
via getNodeIPs and calls https://node-ip:6443.
In deployments where apiserver does not have a certificate for the node
IP this fails with "failed to verify certificate: x509: [...]"
When an explicit k8s address is configured via KubernetesAddr, we want
to use it for the backend health check instead of the node addresses.
Fixes: #1670
Signed-off-by: Mat Kowalski <mko@redhat.com>
AddOrModify only calls leaseMgr.Add inside its `if svcCtx == nil` branch, but
the in-memory lease is removed independently: the cleanup goroutine started by
StartServicesLeaderElection calls leaseMgr.Delete once svcCtx.Ctx is done, and
Manager.Delete drops the lease once its last object goes away.
Several paths cancel the service context without also removing it from svcMap -
the deferred close(stopChan) in watchEndpoint, and the utils.PanicError branch
in AddOrModify. Afterwards svcMap still holds a cancelled context for that UID,
so every later watch event reuses it, skips leaseMgr.Add, and
StartServicesLeaderElection fails on
no existing lease found for service %q with UID %q
for the lifetime of the process. Leader election never restarts and the address
is never re-advertised; only restarting the pod clears it.
This is distinct from #1650, which removed the wg.Wait() deadlock but not this
svcMap <-> leaseMgr desync. Both v1.2.1 and v1.2.2 are affected.
Drop a cancelled service context so the existing code path creates a fresh
context and a fresh lease, restoring the invariant that a service context in
svcMap always has a matching lease in the lease manager.
The alternative - having StartServicesLeaderElection call leaseMgr.Add when Get
returns nil - was rejected because it would attach the lease lifetime to the
service context rather than the watcher context, inverting the intended
ownership model.
Signed-off-by: MaxRink <github@maxrink.de>
In order to workaround https://github.com/FRRouting/frr/issues/22654
where zebra misses updates if multiple are bundled in the same netlink
event, we are introducing a new mechanism.
On every cycle we are re-asserting the route with an idempotent
RouteReplace. Because for a no-op replace kernel emits no notification,
we are alternating the realm attribute on every cycle. Thanks to this,
every re-asstertion is a real change which emits the notification.
Wire impact of this change is none. The prefix, nexthop, metric never
change so BGP daemons do not send UPDATE to peers.
Another option was delete+add but that one would have a real wire impact
if performed too slow.
Signed-off-by: Mat Kowalski <mko@redhat.com>
Entry.Check hardcoded admin.conf/in-cluster config, so the routing
table mode backend gate could never pass on static pod deployments.
The manager's configured kubeconfig is now handed to the backend.
Signed-off-by: Mat Kowalski <mko@redhat.com>
The manager only probed /etc/kubernetes/admin.conf and ~/.kube/config
before falling back to in-cluster config, ignoring k8sConfigPath /
k8s_config_file entirely. OpenShift static pods authenticate with
/etc/kubernetes/kubeconfig, so an explicitly configured path now takes
precedence, with kubernetes_addr able to point at the local API server.
Signed-off-by: Mat Kowalski <mko@redhat.com>
* This enables BFD in kube-vip
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* Fixes from co-pilot
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* Some small logging additionals and a skaffold file
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* Moves logging level back to the global setting
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
---------
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
Add an e2e test for the control-plane health check that verifies route
withdrawal when an apiserver is stopped, re-announcement on recovery,
and graceful withdrawal when kube-vip itself is shut down.
Extract BGP server lifecycle (GoBGP daemon, gRPC client, peer
management) into a reusable bgp.Server type and cluster creation into an
e2e.Cluster type. This replaces the large setupEnv function and
scattered helpers in e2e_bgp_test.go with composable building blocks,
making it simpler to add new BGP test scenarios like the health check.
Consolidate the separate kube-vip-bgp.yaml.tmpl into the main
kube-vip.yaml.tmpl, using the ControlPlaneHealthCheck fields added to
KubevipManifestValues.
Signed-off-by: Guillermo Gaston <ggastonloren@nvidia.com>
In BGP mode without leader election, every kube-vip instance announces
the same VIP. ECMP distributes traffic evenly, but if a node's
kube-apiserver goes down, kube-vip (a static pod tied to kubelet) keeps
advertising the route — sending a fraction of all API traffic into a
black hole.
An optional health check loop now polls the local kube-apiserver and
withdraws the BGP route after a configurable number of consecutive
failures, removing the dead node from the ECMP set. The route is
re-announced once the API server recovers.
Signed-off-by: Guillermo Gaston <ggastonloren@nvidia.com>
* improve logging in election.go and set defaultBGPPort constant
Signed-off-by: Matthew Carpenter <mattcarp88@gmail.com>
* update log messages per code review
Signed-off-by: Matthew Carpenter <mattcarp88@gmail.com>
---------
Signed-off-by: Matthew Carpenter <mattcarp88@gmail.com>
* This fixes the rules for egress allowed-networks
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* lint fix
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* fixes a potential issue with out of bounds array access
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
---------
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* Check BGP config node annotations before creating server
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Add E2E test for BGP config via node annotations
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Escape prefix meta chars when parsing BGP config annotations
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Fail when no peer IP in BGP config annotations
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Stop allowing trailing characters in BGP config annotations
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Compile bgp config annotation regexes outside of loops
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
* Allow setting multi hop via BGP config annotations
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
---------
Signed-off-by: Martynas Deveikis <martynasdev@gmail.com>
Add a Community Tools section with a link to the KubeStellar Console
guided kube-vip installation experience, which provides step-by-step
install with pre-flight checks, validation, troubleshooting, and
rollback support.
Signed-off-by: Andrew Anderson <andy@clubanderson.com>
* services: retry on 403/401 in ServicesWatcher using exponential backoff
On Kubernetes 1.34+, admin.conf uses O=kubeadm:cluster-admins instead
of O=system:masters. On joining control plane nodes, kube-vip starts
before etcd is promoted from learner to full member. RBAC data is not
yet available through the learner etcd, causing a transient 403
Forbidden or 401 Unauthorized on the first Watch call.
Replace the bare Watch call in ServicesWatcher's WatchFunc with
wait.ExponentialBackoffWithContext (from k8s.io/apimachinery/pkg/util/wait,
already in go.mod). Parameters: 2s initial, 2x factor, 0.1 jitter,
30s cap, 10 steps. Non-auth errors are returned immediately. Context
cancellation stops the retry loop cleanly.
Change Processor.rwClientSet from *kubernetes.Clientset to
kubernetes.Interface to enable fake client injection in tests.
watchEndpoint() uses p.clientSet (*kubernetes.Clientset) directly for
CreateRetryWatcher, avoiding an unnecessary type assertion.
Add unit tests covering: 403/401 retry succeeds, context cancellation
during retry. Update CHANGELOG.md.
Fixes: https://github.com/kube-vip/kube-vip/issues/1464
Signed-off-by: Soto Sugita <sotosugi@amazon.co.jp>
* fix(services): refactor watchWithAuthRetry as standalone function
Extract the retry logic into a standalone watchWithAuthRetry function
to avoid changing rwClientSet from *kubernetes.Clientset to
kubernetes.Interface. Tests now directly test watchWithAuthRetry via
closures without fake clientset injection or struct type changes.
Revert Processor.rwClientSet back to *kubernetes.Clientset and remove
the type assertion in watchEndpoint().
Signed-off-by: Soto Sugita <sotosugi@amazon.co.jp>
* fix(services): simplify watchWithAuthRetry tests to table-driven style
Signed-off-by: Soto Sugita <sotosugi@amazon.co.jp>
---------
Signed-off-by: Soto Sugita <sotosugi@amazon.co.jp>
* do not masquerade for local endpoints
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* fix: do not add VIP to lo in wg mode
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* fix: setup policy routing for wg interface
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* refactor: use k8s API types for protocol
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* conservatively apply packet mark
only apply the ct mark as packet mark if it matches our calculated
fwmark
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* use new nftable setup
the nftable setup now uses only one set of chains per tunnel and
utilizes named maps and sets to match NAT the connections properly
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* ensure proper cleanup
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* watch kubernetes endpoints
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* refactor wireguard nftables implementation
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
* use helper for if name determination
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
---------
Signed-off-by: Daniel Nägele <daniel@naegele.dev>
PrometheusCollector() was registering bgpServer.BGPSessionInfoGauge while the worker was writing to Manager.bgpSessionInfoGauge — two separate objects representing the same metric. This caused kube_vip_manager_bgp_session_info to always appear empty in Prometheus.
Signed-off-by: Sebastian Gaiser <sebastiangaiser@users.noreply.github.com>
* Now will ensure egress rules are cleaned for nft-internal
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
* Fixed missing IPv6 rule
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
---------
Signed-off-by: Dan Finneran <dan@thebsdbox.co.uk>
Prevents log spam in control-plane-only deployments where
ServiceInstances is always empty. The UPNP refresh goroutine
still runs but no longer logs every 5 minutes when there's
nothing to refresh.
Fixes noise in SIEM systems and log aggregators.
Signed-off-by: Olli Hauer <ohauer@gmx.de>
PR #1252 (fix for #1243) removed the guard that prevented adding the
service IP to the interface in routing table mode. This made AddIP()
unconditional in StartLoadBalancerService(), causing the LoadBalancer IP
to be added to the interface on ALL nodes.
In no-election routing table mode (vip_leaderelection=false,
svc_election=false), this leads to traffic blackholing: every node has
the VIP bound to its interface, but only the node with local endpoints
can actually serve traffic when externalTrafficPolicy is Local.
The original code correctly guarded AddIP() behind `!c.EnableRoutingTable`
because in L3 modes (routing table / BGP), traffic is attracted via
routing protocols, not by having the IP present on the interface. The
endpoint watchers (endpoints_routing_table.go, endpoints_bgp.go) manage
routes/advertisements based on local endpoint presence.
Restore the guard and extend it to also cover BGP mode:
- Routing table mode: only routes are managed (by endpoint watcher or
leader), no IP on interface
- BGP mode: only BGP advertisements are managed, no IP on interface
- ARP/L2 mode: IP is added to interface (unchanged behavior)
Control plane (cp_enable) is unaffected as vipService() has its own
independent AddIP() call.
Existing stale IPs from the buggy version are cleaned up automatically
on restart, as StartLoadBalancerService() unconditionally calls
DeleteIP() before the now-guarded AddIP().
Signed-off-by: Christopher Dziomba <christopher.dziomba@telekom.de>
* fix common lease fix from 1.0.1
Test coverage specific to this issue
- TestManager_LeaderElectionRestartScenario - Simulates the bug from the issue
Additional tests for leases
- TestManager_Add_NewLease - Verifies new lease creation
- TestManager_Add_ExistingLease - Verifies returning existing lease
- TestManager_Delete_DecrementCounter - Verifies reference counting
- TestManager_Delete_CancelsContext - Verifies context cancellation on delete
- TestManager_Add_AfterDelete_CreatesNewLease - Critical test for the bug fix - verifies a new lease is created after delete
- TestManager_Add_DifferentServices - Verifies different services get different leases
- TestManager_Add_SameNameDifferentNamespace - Verifies namespace isolation
- TestManager_ConcurrentAccess - Verifies thread safety
- TestLease_StartedChannel - Verifies Started channel behavior
- TestGetName_WithoutAnnotation - Verifies default lease naming
- TestGetName_WithAnnotation - Verifies custom lease naming
- TestUsesCommon - Verifies common lease detection
- TestManager_CommonLeaseScenario - Verifies the common lease feature still works
Affects issue #1377
Signed-off-by: Brian Davis <dbrian@vmware.com>
* handle 0 LB addresses
Signed-off-by: Brian Davis <slimm609@gmail.com>
Signed-off-by: Brian Davis <dbrian@vmware.com>
* update tests for hanging connections
Signed-off-by: Brian Davis <slimm609@gmail.com>
* fix lint and remaining tests
Signed-off-by: Brian Davis <slimm609@gmail.com>
* fix failing tests for waiting for lease
Signed-off-by: Brian Davis <slimm609@gmail.com>
* handle race in intergration test
Signed-off-by: Brian Davis <slimm609@gmail.com>
---------
Signed-off-by: Brian Davis <dbrian@vmware.com>
Signed-off-by: Brian Davis <slimm609@gmail.com>
The annotation `kube-vip.io/upnp-lease-duration` takes in a duration where the string is parseable by `time.ParseDuration`.
There is no new configuration option that would allow setting this globally, since this new feature is most helpful in limited cases (such as incorrect implementations that have trouble with certain values).
There is a minimal test added for the value returned by the new private helper `upnpLeaseDurationForService`. Due to a lack of dependency injection in `service.Processor`'s `upnpMap`, it is infeasible to add a more complete test at this time, to check what would be passed, exactly, into `AddPinholeCtx` and `AddPortMapping`.
Signed-off-by: Ivan Vučica <ivan@vucica.net>
Signed-off-by: Ivan Vučica <ivucica@google.com>
Fixes: #1349
This moves the `log.Info` call inside the check for nil-ness of the
`gw.WANIPv6FirewallControlClient`. A UPnP portmap device that
has no IPv6 support crashes without this check.
To compensate, this adds logging statements for the `PortForward`
case.
Signed-off-by: Ivan Vučica <ivan@vucica.net>
Signed-off-by: Ivan Vučica <ivucica@google.com>
Fixes: #1335
- ipv6 has duplicate address dectection which prevents perserving the VIP on the old node
Signed-off-by: Brian Davis <slimm609@gmail.com>
Signed-off-by: Brian Davis <dbrian@vmware.com>
When in arp mode, when preserveVipOnLeadershipLoss is true, when a node loses leadership (or can't keep it),
this will stop performing ARPs but will wait until a new leader is elected before deleting the arp.
when the flag is set to false (default) it continue to function like normal.
Signed-off-by: Brian Davis <slimm609@gmail.com>
Signed-off-by: Brian Davis <dbrian@vmware.com>
Implements Issue #1301 - Adds support for dumping current configuration
when SIGUSR1 signal is received by the kube-vip process.
Changes:
- Add SIGUSR1 signal handling in all manager start methods
- Implement configuration dump functionality in pkg/manager/manager_dump.go:
* dumpConfiguration() - Main dump coordinator
* 7 helper methods for different configuration sections
- Update signal handlers to use switch statement pattern
- Add comprehensive unit tests (5 tests, all passing)
- Add E2E test for signal handling
Implementation details:
- Thread-safe with mutex protection
- Non-disruptive: process continues after dump
- Output format: human-readable plaintext via stdout
- File organization follows project convention (manager_*.go pattern)
Co-authored-by: SteveYi <steveyiyo@steveyi.net>
Signed-off-by: thc1006 <84045975+thc1006@users.noreply.github.com>
* Moved functions from mod pkg vip to pkg utils
* remove the dependency of the kubevip config pkg on the bgp pkg
* introduce BGPConfig and BGPPeer to kubevip package and migrate label from node labeler
* Use the new BGPConfig and BGPPeer type of the kubevip pkg
* Removed utils functions from vip pkg and refactor to call utils instead
* migrate from pkg vip to utils for generic IP funcs
* migrate common annotations and labels into a central place + support for hostnames
* if any change happens we want to reconcile it here
* fix e2e tests which relied also on the vip package instead of utils
* Better debug logging
* Added info if it is egress
* added missing condition to dhcp specific actions
* Disable the service before cancelling the context
* lets try auto,auto instead of /32 and nothing
* Let's reset svcCtx to be nil to ensure a new context when the previous was garbage collected
* Added a space for project wide constants
---------
Signed-off-by: Cellebyte <marcel.fest@live.de>
fix table addIP missing
add more debug lines
start service listener before content plane because content plane is blocking main thread
Signed-off-by: Thorsten Bonhagen <Thorsten.Bonhagen@tbon.de>
- Change os.WriteFile permissions from 0644 to 0600 in config_file_test.go
- Addresses GoSec G306 linter requirement for secure file permissions
- Ensures test files are readable/writable by owner only
Signed-off-by: Yuval Weisz <yuval.weisz@vastdata.com>
This commit adds extensive unit tests for the new configuration file features:
Test Coverage:
- LoadConfigFromFile() function with YAML and JSON parsing
- MergeConfigFromFile() function with priority logic testing
- Configuration merging with complex nested structures (BGP, leader election)
- Error handling for invalid files, unsupported formats, and missing files
- Environment variable integration for config_file
- Priority validation: CLI flags > env vars > config file
- Boolean flag merging behavior
- BGP configuration merging
- Leader election configuration merging
Files:
- pkg/kubevip/config_file_test.go: New comprehensive test suite (550+ lines)
- pkg/kubevip/config_generator_test.go: Enhanced with config_file env var tests
Test Structure:
- TestLoadConfigFromFile: Tests JSON/YAML parsing and error cases
- TestMergeConfigFromFile: Tests configuration priority and merging
- TestMergeConfigValues: Tests detailed field-by-field merging logic
- TestParseEnvironmentConfigFile: Tests config_file environment variable
The tests validate all aspects of the configuration file implementation
including edge cases, error scenarios, and complex configuration structures.
All tests follow Go testing best practices with table-driven test patterns.
Signed-off-by: Yuval Weisz <yuval.weisz@vastdata.com>
This commit implements configuration file support for kube-vip, allowing
users to specify configuration through JSON or YAML files.
Features:
- Added --config-file command line flag that accepts JSON/YAML file paths
- Added config_file environment variable support
- Implemented proper configuration priority: CLI flags > env vars > config file
- Added comprehensive configuration merging for all fields including BGP,
leader election, routing table, and load balancer settings
- Supports both JSON and YAML file formats with automatic detection
- Maintains full backward compatibility with existing deployments
Changes:
- pkg/kubevip/config_envvar.go: Added configFile constant
- pkg/kubevip/config_types.go: Added ConfigFile field to Config struct
- pkg/kubevip/config_environment.go: Added LoadConfigFromFile() and
MergeConfigFromFile() functions with comprehensive merging logic
- cmd/kube-vip.go: Integrated config file loading into service and manager commands
Usage:
kube-vip manager --config-file /etc/kube-vip/config.yaml
export config_file=/etc/kube-vip/config.json && kube-vip manager
This enhancement significantly improves configuration management for complex
kube-vip deployments while maintaining the existing behavior and patterns.
Signed-off-by: Yuval Weisz <yuval.weisz@vastdata.com>
This causes IPv6 source address selection according to RFC 3484 to
ignore VIPs when choosing which address the host should use for egress
communication.
Signed-off-by: Jan-Philipp Litza <janphilipp@litza.de>
fmt target is stale, just removing it, also simplify target is not working under 1.21 toolchain,
update it as well.
Signed-off-by: Lin Lin <linlin152@foxmail.com>
When using DHCP for LB services, the resulting IP was assigned to the
`serviceInterface` while most (not all) DHCP communication was done
through a per-service `macvlan` interface that is created on demand.
This has been the cause of DHCP lease renewal failures for some users,
as the response packets from the server never reached kube-vip. For more
details, see issue #871.
To remedy this, the primary interface used for a service is now being
set to the `macvlan`. Consequently, the IP address is also assigned to
it.
As a result, all traffic related to an LB service (DHCP or not) is now
originating from and sent to the per-service `macvlan` interface that
is tied to the user-configured `serviceInterface`.
Fixes#871
Signed-off-by: Til Blechschmidt <me@tibl.dev>
In order to run the kubelet in kind containers on the vms provided by
github, the kubelet needed some extra configuration.
Signed-off-by: Guillermo Gaston <gaslor@amazon.com>
This adds a new leader election mode that instead of using the kube api
server to obtain a lease, it relies solely on etcd.
By removing the dependency on the api server, we can use it even before
the api server is up, before cluster creation.
In an external etcd topology, this way we can make the api server point
to the VIPs instead of to the etcd machines IPs. This configuration
isolates the CP configuration from the etcd machine IPS. It's is super
convenient to avoid having to roll new control plane nodes when the etcd
nodes change.
Signed-off-by: Guillermo Gaston <gaslor@amazon.com>
* Fix 2 broken tests
* Fix e2e ARP tests: killing one node in a 2 CP node cluster makes etcd
lose quorum. So it can't elect a new leader if the node we happen to
kill was the etcd leader.
* Separate unit tests, e2e tests, linter and scans in different jobs so
they run concurrently.
Signed-off-by: Guillermo Gaston <gaslor@amazon.com>
This feature is related to #611, to configure the
`CiliumEgressGatewayPolicy` EgressIP correctly.
As this is not a very common usage for this project, there is a default
disabled configuration flag added, `enable_node_labeling`.
Signed-off-by: Mario Trangoni <mjtrangoni@gmail.com>
Using Equinix Metal annotations was limited to only the first BGP peer. This PR adds support for multiple BGP peer by looking at all bgp peer node annotations.
Signed-off-by: Enkel Prifti <enkelprifti@live.com>
The Equinix Metal API integration was missing support for BGP session passwords so this PR adds the BGP password parameter.
Signed-off-by: Enkel Prifti <enkelprifti@live.com>
Skip service security configuration for the service whose annotation kube-vip.io/ignore-service-security is true
Signed-off-by: Canwu Yao <yaocanwu@gmail.com>
When IPv6 addresses are present in node.Status.Addresses, the
IPVSLoadBalancer parses the addresses and attempts to add them as an
IPv4 destinations. This results in useless entries in the service table
that only hold the last 32 bits of address.
This change does two things:
- uses the appropriate address family when creating the service
- ignores backend addresses that use a different address family than the
service
This avoids the immediate problem of using the wrong address family for
IPv6 destinations and the useless entries in the service table.
Signed-off-by: Matthew Sykes <matthew.sykes@gmail.com>
Add new annotation kube-vip.io/loadbalancerIPs to specify the loadbalancer ip for service
Now ip address fetched from loadbalancer service are first fetched from annotation, then fallback to service spec
Unit test
Signed-off-by: lubronzhan <lzhan@vmware.com>
Remove the address from in the interface case that a duplicate address is detected.
Without this change, kube-vip will take no corrective action, and the
address will remain in dadfailed state. Removing and re adding the
address causes duplicate address detection to happen again, hopefully
successfully the next time.
We suspect dadfailed happens when a new leader is elected and the old
leader is too slow or fails to delete the IP address.
Co-authored-by: Aidan Obley <aobley@vmware.com>
Co-authored-by: Christian Ang <angc@vmware.com>
Signed-off-by: Tyler Schultz <tschultz@vmware.com>
Ability to specify BGP port is removed, for two reasons:
1. IPv6 peer addresses contain colons, and the SpiltN func breaks IPv6 addresses.
2. Typical network devices do not allow changing BGP port, so this is rarely used.
Signed-off-by: zyxwvu Shi <i@shiyc.cn>
MP-BGP protocol requires IPv6 prefixes to be advertised in a path attribute called MP_REACH_NLRI. Without the attribute non-IPv4 prefixes can not be advertised. This prevents IPv6 loadBalancerIps and control plane addresses from being advertised to the network.
Signed-off-by: zyxwvu Shi <i@shiyc.cn>
According to UpdatePathAttrs in gobgp internal/pkg/table/path.go, gobgp will fill NEXT_HOP with BGP session local address if given NEXT_HOP is an unspecified address, such as 0.0.0.0 and ::. It is better to use that address as NEXT_HOP, since the BGP TCP connection ensures the address reaches the node.
See: https://github.com/osrg/gobgp/blob/v3.10.0/internal/pkg/table/path.go#L223
Signed-off-by: zyxwvu Shi <i@shiyc.cn>
Without this specific ClusterRole rule, kube-vip would not be able to listen for `endpoints` changes when deployed as a DaemonSet, thus causing the IP addresses not being announced and the following error message every second:
```
E1227 20:37:20.290479 1 retrywatcher.go:130] "Watch failed" err="unknown (get endpoints)"
```
The macvlan interface could not be deleted until the DHCP client has
released the IP.
If the network manager in the operating system uses DHCP to obtain an IP
for the network card, it will occupy the DHCP client port. In this case
the release function will fail because the unicast connection with UDP
socket need the same port. Update dhcp package and use a raw socket.
Signed-off-by: yaocw2020 <yaocanwu@gmail.com>
Previous commits addressed the issue of interface being incorrectly marked as
down for loopback (1a4465e) and point-to-point (051bb1f) interfaces by directly
passing the test when the interface is identified a any of those types. Both
commits failed to address the core issue, those interfaces (and many others) do
not publish their operational state resulting in the state UNKOWN. With this
commit, now interfaces with unknown status are accepted but the user is warned as
he needs to manually ensure that the interface is ready to handle traffic.
Fix#385
Signed-off-by: Claudio Yanes <me@claudio4.com>
The kube-vip chooses the default interface based on the default
route. Once the default route changes, the default interface may be
invalid. In this case, it would be better to crash the process. The pod
will restart immediately if the kube-vip is deployed as a daemonset.
Signed-off-by: yaocw2020 <yaocanwu@gmail.com>
In some cases, kube-vip will start to serve before the interface is not
existed or not up. We should make sure the interface is valid.
Signed-off-by: yaocw2020 <yaocanwu@gmail.com>
When the manager process is started without the `--vip` flag, it will
panic during initialization. This is because the `nil` result from
`net.ParseIP("")` is passed to `ipvs.NewIP()`.
This change passes the resolved address from `cluster.Network.IP()`
instead of the possibly-empty VIP from the configuration.
Signed-off-by: Matthew Sykes <matthew.sykes@gmail.com>
The current node watcher uses a label selector of the form
`node-role.kubernetes.io/control-plane=`; this does not work correctly.
The label selector should be `node-role.kubernetes.io/control-plane" or
`node-role.kubernetes.io/control-plane=true` to select the control-plane
nodes.
Without these changes, the IPVS tables are never updated with the
control plane nodes and clients making requests to the VIP will fail
with a "connection refused" error.
```
$ kubectl get nodes -l node-role.kubernetes.io/control-plane=
No resources found
$ kubectl get nodes -l node-role.kubernetes.io/control-plane=true
NAME STATUS ROLES AGE VERSION
pi4-00 Ready control-plane,etcd,master 21h v1.22.3+k3s1
pi4-01 Ready control-plane,etcd,master 20h v1.22.3+k3s1
pi4-02 Ready control-plane,etcd,master 20h v1.22.3+k3s1
$ kubectl get nodes -l node-role.kubernetes.io/control-plane
NAME STATUS ROLES AGE VERSION
pi4-00 Ready control-plane,etcd,master 21h v1.22.3+k3s1
pi4-01 Ready control-plane,etcd,master 20h v1.22.3+k3s1
pi4-02 Ready control-plane,etcd,master 20h v1.22.3+k3s1
```
Signed-off-by: Matthew Sykes <matthew.sykes@gmail.com>
KVVERSION needs to be preceeded with `$` for shell expansion of the variable.
`kubectl` is unlikely to be a binary in the current directory and is likely to be in `$PATH`
Use Equinix Metal credentials when available with EIP configuration
not just BGP configuration.
Signed-off-by: Jason DeTiberus <detiber@users.noreply.github.com>
- Tolerate more than just the node-role.kubernetes.io/master taint, this allows
the daemonset to schedule prior to CNI being deployed.
- Switch from using a nodeSelector to using nodeAffinity
- Allows scheduling even if the node label does not match the value (for the node-role label, the value is generally ignored).
- Add support for the control-plane node role rather than just master.
Signed-off-by: Jason DeTiberus <detiber@users.noreply.github.com>
I'll help you add a suggestion. Unfortunately, I can't directly add a suggestion to an existing comment through the API. However, here's what I recommend:
**Option 1: Reply with a suggestion**
Create a new comment with a suggested fix:
```suggestion
failed to get an IPv6 address after %d attempt(s), giving up, error: %s
```
**Option 2: Edit your existing comment**
Update your comment to include the suggestion details pointing out that line 284 in the error message says "IPv4" but should say "IPv6" since this is the DHCPv6Client.
Would you like me to create a new reply comment with the suggestion instead?
All notable changes to this project will be documented in this file.
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
## [Unreleased]
### Fixed
- Propagate `bgp_attach_ip_to_interface` into per-service config so it attaches BGP-mode Service VIPs to the interface as configured.
- Add a configurable kube-vip instance name and use it to isolate internal nftables egress tables, persist table ownership on Services, and migrate per-Service chains without affecting other deployments. Fixes #1634.
- Retry on 403 Forbidden and 401 Unauthorized in `ServicesWatcher` at startup with exponential backoff. Fixes #1464.
- Reintroduce BGP config via node annotations. Fixes #1488.
- Fail fast in runtime `manager` and `service` paths when legacy `vip_address` is used without `vip_subnet` in control-plane ARP, BGP, or Routing Table mode.
- Cancel the mode context on init or configuration failure before waiting on goroutines during shutdown.
### Added
- Configurable control-plane health check for BGP mode without leader election
- Polls a configurable HTTP(S) endpoint (e.g. `https://localhost:6443/livez`) to verify the exposed service is healthy (usually the local kube-apiserver)
- Withdraws the BGP route after a configurable number of consecutive failures, removing the unhealthy node from the ECMP set
- Re-announces the route automatically once the endpoint recovers
- Gracefully withdraws the route on shutdown (SIGTERM)
- Supports custom CA certificates for TLS verification
- Configuration via environment variables or CLI flags:
-`control_plane_health_check_address` / `--controlPlaneHealthCheckAddress`: URL to poll
-`control_plane_health_check_period_seconds` / `--controlPlaneHealthCheckPeriodSeconds`: interval between checks (default: 5)
- Starts service handling path for opted-in endpointless Cluster services while preserving default endpoint-gated behavior for non-opt-in services and `Local` policy
- Added endpoint behavior tests and README usage documentation
- Added support in ipoib interfaces in ARP mode. Fixes #694
### Changed
- BGP mode now honours `enable_leader_election` for services: a single global services leader advertises the service VIPs instead of every node advertising them. Deployments that enabled `enable_leader_election` for the control plane and relied on ECMP/multipath for services must unset it (or switch to `enable_service_election`) to keep the previous datapath. kube-vip logs a warning on startup when this path is taken.
- Updated signal handlers in manager_arp.go, manager_bgp.go, manager_wireguard.go, and manager_table.go to use switch statement pattern for handling multiple signals (SIGUSR1, SIGINT, SIGTERM)
- wireguard.go now manages a complete wireguard interface on the current network namespace
- manager_wireguard.go uses the new wireguard.go implementation
## [v1.0.1] - Previous Release
### Previous changes
- See git history for changes prior to CHANGELOG.md introduction
@@ -113,8 +113,8 @@ and *merged* sorts of commits.
To make it easier for reviewers to review your PR, consider the following:
1. Follow the golang [coding conventions](https://github.com/golang/go/wiki/CodeReviewComments).
2. Format your code with `make golangci-fix`; if the [linters](ci/README.md) flag an issue that
cannot be fixed automatically, an error message will be displayed so you can address the issue.
2. Format your code with `make simplify` to automatically fix formatting issues.
2. Lint your code with `make check`; if the linters flag an issue that cannot be fixed automatically, an error message will be displayed so you can address the issue.
GOMAXPROCS=4TEST_MODE=arp K8S_IMAGE_PATH=kindest/node:$(K8S_VERSION)E2E_IMAGE_PATH=$(REPOSITORY)/$(TARGET):$(DOCKERTAG) go run github.com/onsi/ginkgo/v2/ginkgo --tags=e2e -v $(GINKGO_PARALLEL)$(GINKGO_ARGS) ./testing/e2e
e2e-tests-rt:get-whoami
GOMAXPROCS=4TEST_MODE=rt K8S_IMAGE_PATH=kindest/node:$(K8S_VERSION)E2E_IMAGE_PATH=$(REPOSITORY)/$(TARGET):$(DOCKERTAG) go run github.com/onsi/ginkgo/v2/ginkgo --tags=e2e -v $(GINKGO_PARALLEL)$(GINKGO_ARGS) ./testing/e2e
e2e-tests-bgp:get-whoamiget-gobgp
GOMAXPROCS=4TEST_MODE=bgp K8S_IMAGE_PATH=kindest/node:$(K8S_VERSION)E2E_IMAGE_PATH=$(REPOSITORY)/$(TARGET):$(DOCKERTAG) go run github.com/onsi/ginkgo/v2/ginkgo --tags=e2e -v $(GINKGO_PARALLEL)$(GINKGO_ARGS) ./testing/e2e
e2e-tests-etcd:get-whoami
GOMAXPROCS=4K8S_IMAGE_PATH=kindest/node:$(K8S_VERSION)E2E_IMAGE_PATH=$(REPOSITORY)/$(TARGET):$(DOCKERTAG) go run github.com/onsi/ginkgo/v2/ginkgo --tags=e2e -v $(GINKGO_PARALLEL)$(GINKGO_ARGS) ./testing/e2e/etcd
e2e-tests:e2e-tests-arpe2e-tests-rte2e-tests-bgp
service-tests:
$(MAKE) -C testing/e2e/e2e dockerLocal
E2E_IMAGE_PATH=$(REPOSITORY)/$(TARGET):$(DOCKERTAG) go run ./testing/services -Services -simple -deployments -leaderActive -leaderFailover -localDeploy -electionFaults -egress -egressIPv6 -dualStack -egressInternal
trivy:dockerx86ActionIPTables
docker run -v /var/run/docker.sock:/var/run/docker.sock aquasec/trivy:0.47.0 \
[](https://github.com/kube-vip/kube-vip/actions/workflows/main.yaml) [](https://insights.linuxfoundation.org/project/kube-vip) [](https://insights.linuxfoundation.org/project/kube-vip)
## Overview
Kubernetes Virtual IP and Load-Balancer for both control plane and Kubernetes services
@@ -16,6 +18,8 @@ The idea behind `kube-vip` is a small self-contained Highly-Available option for
**NOTE:** All documentation of both usage and architecture are now available at [https://kube-vip.io](https://kube-vip.io).
For upgrading an existing install in place (static Pod or DaemonSet), see the [upgrade guide](https://kube-vip.io/docs/upgrade/).
## Features
Kube-Vip was originally created to provide a HA solution for the Kubernetes control plane, over time it has evolved to incorporate that same functionality into Kubernetes service type [load-balancers](https://kubernetes.io/docs/concepts/services-networking/service/#loadbalancer).
@@ -30,7 +34,8 @@ Kube-Vip was originally created to provide a HA solution for the Kubernetes cont
- Service LoadBalancer address pools per namespace or global
- Service LoadBalancer address via (existing network DHCP)
- Service LoadBalancer address exposure to gateway via UPNP
-... manifest generation, vendor API integrations and many nore...
-Egress! Kube-vip will utilise a service loadbalancer as both the ingress and **egress** for a pod.
- ... manifest generation, vendor API integrations and many more...
## Why?
@@ -55,4 +60,81 @@ All of these would require a separate level of configuration and in some infrast
## Troubleshooting and Feedback
### SELinux and IPVS kernel modules
When using IPVS load balancing on nodes with SELinux enforcing, kube-vip may be
blocked from requesting kernel modules from inside the container. Symptoms can
include the kube-vip pod entering `Error` or `CrashLoopBackOff`, logs that show
`ensure IPVS kernel modules are loaded`, or audit denials for `module_request`
from `container_t`.
Load the required IPVS modules on every node that can run kube-vip before
deploying it:
```shell
sudo modprobe ip_vs
sudo modprobe ip_vs_rr
```
To persist this across reboots, add the modules to a file such as
`/etc/modules-load.d/kube-vip-ipvs.conf`:
```text
ip_vs
ip_vs_rr
```
Preloading only the required modules is preferred to enabling the SELinux
`domain_kernel_load_modules` boolean for containers.
### Gateway API `LoadBalancer` services with no endpoints
Some Gateway API controllers create `LoadBalancer` services that intentionally have no Endpoints/EndpointSlices backends.
If you want kube-vip to reconcile such a service, opt in with:
- Works only with `externalTrafficPolicy: Cluster`
- No effect for `Local`
- Default endpoint-gated behavior remains unchanged for services without this annotation
Please raise issues on the GitHub repository and as mentioned check the documentation at [https://kube-vip.io](https://kube-vip.io/).
## Community Tools
- **[KubeStellar Console — Guided kube-vip Install](https://console.kubestellar.io/missions/install-kube-vip)** — A step-by-step guided installation experience for kube-vip with pre-flight checks, validation, troubleshooting, and rollback support.
## Contributing
Thanks for taking the time to join our community and start contributing! We welcome pull requests. Feel free to dig through the [issues](https://github.com/kube-vip/kube-vip/issues) and jump in.
:warning: This project has issue compiling on MacOS, please compile it on linux distribution
Additionally it is now relatively easy and quick to develop with [skaffold](https://skaffold.dev/), and the `skaffold.yaml` exists within the root folder of the gir repository.
3. Create a load balancer range `configMap` from the kind cluster
4. Apply the CCM manifest
5. Start skaffold with `skaffold dev`
6. Start developing and see changes applied in real-time.
## Star History
[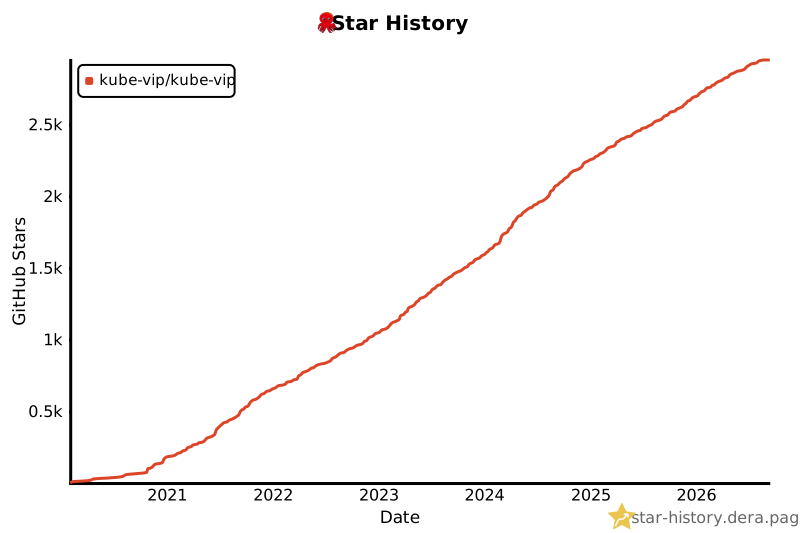](https://star-history.dera.page/#kube-vip/kube-vip&type=date)
This document outlines the roadmap for the **kube-vip** project and only covers the technologies within this particular project, other projects that augment or provide additional functionality (such as cloud-providers) may have their own roadmaps in future. The functionality for **kube-vip** has grown either been developed organically or through real-world needs, and this is the first attempt to put into words a plan for the future of **kube-vip** and will additional evolve over time. This means that items listed or detailed here are not neccessarily set in stone and the roadmap can grow/shrink as the project matures. We definitely welcome suggestions and ideas from everyone about the roadmap and **kube-vip** features. Reach us through Issues, Slack or email <catch-all>@kube-vip.io.
This document outlines the roadmap for the **kube-vip** project and only covers the technologies within this particular project, other projects that augment or provide additional functionality (such as cloud-providers) may have their own roadmaps in future. The functionality for **kube-vip** has grown either been developed organically or through real-world needs, and this is the first attempt to put into words a plan for the future of **kube-vip** and will additional evolve over time. This means that items listed or detailed here are not necessarily set in stone and the roadmap can grow/shrink as the project matures. We definitely welcome suggestions and ideas from everyone about the roadmap and **kube-vip** features. Reach us through Issues, Slack or email <catch-all>@kube-vip.io.
## Release methodology
The **kube-vip** project attempts to follow a tick-tock release cycle, this typically means that one release will come **packed** with new features where the following release will come with fixes, code sanitation and performane enhancements.
The **kube-vip** project attempts to follow a tick-tock release cycle, this typically means that one release will come **packed** with new features where the following release will come with fixes, code sanitation and performance enhancements.
## Roadmap
@@ -13,12 +13,12 @@ The **kube-vip** project offers two main areas of functionality:
- HA Kubernetes clusters through a control-plane VIP
- Kubernetes `service type:LoadBalancer`
Whilst both of these functions share underlying technologies and code they will have slightly differening roadmaps.
Whilst both of these functions share underlying technologies and code they will have slightly differing roadmaps.
### HA Kubernetes Control Plane
- **Re-implememt LoadBalancing** - due to a previous request the HTTP loadbalancing was removed leaving just HA for the control plane. This functionality will be re-implemented either through the original round-robin HTTP requests or utilising IPVS.
- **Utilise the Kubernetes API to determine additional Control Plane members** - Once a single node cluster is running **kube-vip** could use the API to determine the additional members, at this time a Cluster-API provider needs to drop a static manifest per CP node.
- **Re-implement LoadBalancing** - due to a previous request the HTTP loadbalancing was removed leaving just HA for the control plane. This functionality will be re-implemented either through the original round-robin HTTP requests or utilising IPVS.
- **Utilise the Kubernetes API to determine additional Control Plane members** - Once a single node cluster is running **kube-vip** could use the API to determine the additional members, at this time a Cluster-API provider needs to drop a static manifest per CP node.
- **Re-evaluate raft** - **kube-vip** is mainly designed to run within a Kubernetes cluster, however it's original design was a raft cluster external to Kubernetes. Unfortunately given some of the upgrade paths identified in things like CAPV moving to leaderElection within Kubernetes became a better idea.
## Kubernetes `service type:LoadBalancer`
@@ -29,7 +29,7 @@ Whilst both of these functions share underlying technologies and code they will
## Global **Kube-Vip** items
- **Improved metrics** - At this time the scaffolding for monitoring exists, however this needs drastically extending to provide greater observability to what is happening within **kube-vip**
- **Windows support** - The Go SDK didn't support the capability for low-levels sockets for ARP originally, this should be revisted.
- **Windows support** - The Go SDK didn't support the capability for low-levels sockets for ARP originally, this should be revisited.
// kubeadm adds two subcommands for managing a vip during a kubeadm init/join
@@ -28,134 +23,137 @@ func init() {
varkubeKubeadm=&cobra.Command{
Use:"kubeadm",
Short:"Kubeadm functions",
Run:func(cmd*cobra.Command,args[]string){
cmd.Help()
// TODO - A load of text detailing what's actually happening
Long:`This command group provides utilities for generating static Pod manifests specifically tailored for the kubeadm bootstrapping process.
It contains two subcommands:
- init: Generates a manifest to be used during 'kubeadm init' on the first control-plane node.
- join: Generates a manifest to be used during 'kubeadm join' for additional control-plane nodes.
The generated YAML manifest should be saved to the kubeadm static Pod directory (typically /etc/kubernetes/manifests/) so that kubeadm launches the kube-vip static Pod automatically.`,
Run:func(cmd*cobra.Command,_[]string){
_=cmd.Help()
},
}
varkubeKubeadmInit=&cobra.Command{
Use:"init",
Short:"kube-vip init",
Long:"The \"init\" subcommand will generate the Kubernetes manifest that will be started by kubeadm through the kubeadm init process",
Run:func(cmd*cobra.Command,args[]string){
// Set the logging level for all subsequent functions
log.SetLevel(log.Level(logLevel))
Long:`The 'init' subcommand generates a Kubernetes Pod manifest that kubeadm will start as a static Pod during the cluster initialisation phase.
This manifest runs kube-vip on the first control-plane node to advertise the Virtual IP (VIP) for the API server. The VIP is typically configured using ARP (Layer 2) or BGP (dynamic routing).
Required flags for this command:
--interface : The network interface to bind the VIP to (e.g., eth0).
--vip or --address : The Virtual IP address or DNS name to use.
// Set the logging level for all subsequent functions
log.SetLevel(log.Level(logLevel))
Long:`The 'join' subcommand generates a Kubernetes Pod manifest for additional control-plane nodes joining an existing cluster via 'kubeadm join'.
It functions identically to the 'init' subcommand, but is intended for secondary control-plane nodes. It validates that the kubeconfig file (specified by --config, defaulting to /etc/kubernetes/admin.conf) exists on the node to ensure the node can authenticate with the cluster.
Required flags for this command:
--interface : The network interface to bind the VIP to.
--vip or --address : The Virtual IP address or DNS name (must match the VIP used during 'init').
// - Pod spec manifest, mainly used for a static pod (kubeadm)
// - Daemonset manifest, mainly used to run kube-vip as a deamonset within Kubernetes (k3s/rke)
// - RBAC manifest, used to generate the RBAC permissions for kube-vip
//var inCluster bool
vartaintbool
vartaint,role,rolebinding bool
funcinit(){
kubeManifest.PersistentFlags().BoolVar(&inCluster,"inCluster",false,"Use the incluster token to authenticate to Kubernetes")
kubeManifest.PersistentFlags().StringVar(&image,"image","ghcr.io/kube-vip/kube-vip","Define a hardcoded image with or without tag for the manifest")
kubeManifestDaemon.PersistentFlags().BoolVar(&taint,"taint",false,"Taint the manifest for only running on control planes")
kubeManifestRbac.PersistentFlags().BoolVar(&role,"role",false,"Generate only a Role inside the serviceNamespace access")
kubeManifestRbac.PersistentFlags().BoolVar(&rolebinding,"rolebinding",false,"Generate only a RoleBinding for namespaced access")
kubeManifest.AddCommand(kubeManifestPod)
kubeManifest.AddCommand(kubeManifestDaemon)
kubeManifest.AddCommand(kubeManifestRbac)
}
varkubeManifest=&cobra.Command{
Use:"manifest",
Short:"Manifest functions",
Run:func(cmd*cobra.Command,args[]string){
cmd.Help()
// TODO - A load of text detailing what's actually happening
Long:`This command group provides flexible manifest generation for deploying kube-vip in various Kubernetes environments.
Unlike the 'kubeadm' subcommands, which are tightly coupled to kubeadm's static Pod requirements, these generators produce standard Kubernetes manifests (Pod, DaemonSet, RBAC) that can be used with any Kubernetes distribution (e.g., k3s, RKE, or vanilla Kubernetes).
Subcommands:
pod : Generates a standalone Pod manifest (similar to a static pod).
daemonset : Generates a DaemonSet manifest to run kube-vip on selected nodes.
rbac : Generates the necessary ServiceAccount, Role/ClusterRole, and Binding manifests.
All output is written to stdout as YAML, typically piped to 'kubectl apply -f -' or saved to a file.`,
Run:func(cmd*cobra.Command,_[]string){
_=cmd.Help()
},
}
varkubeManifestPod=&cobra.Command{
Use:"pod",
Short:"Generate a Pod Manifest",
Run:func(cmd*cobra.Command,args[]string){
// Set the logging level for all subsequent functions
log.SetLevel(log.Level(logLevel))
Long:`Generate a standalone Pod manifest for kube-vip.
This is ideal for environments that do not use DaemonSets or where you want to run kube-vip as a static Pod (similar to the 'kubeadm' subcommand, but without kubeadm-specific assumptions). It includes all the necessary container specifications, volumes, and environment variables derived from the provided flags.
Key flags:
--interface : Network interface for the VIP.
--vip or --address : The Virtual IP address or DNS name.
--image : Override the container image (default: ghcr.io/kube-vip/kube-vip).
The manifest is generated based on the current configuration flags set on the root command.
// Set the logging level for all subsequent functions
log.SetLevel(log.Level(logLevel))
Long:`Generate a DaemonSet manifest to run kube-vip across multiple nodes.
This is the recommended deployment method for production clusters running kube-vip as a service. It ensures that kube-vip runs on all control-plane nodes (or selected nodes via tolerations) and can handle both control-plane HA and service load-balancing.
Flags specific to this subcommand:
--taint : Adds a toleration to the DaemonSet so that pods are scheduled only on nodes with the control-plane taint (node-role.kubernetes.io/control-plane:NoSchedule). This is essential for control-plane-only deployments.
All other standard kube-vip flags (--interface, --vip, --enableARP, --enableBGP, etc.) are respected and embedded into the DaemonSet pod template.
Long:`Generate the RBAC (Role-Based Access Control) manifests required for kube-vip to interact with the Kubernetes API.
kube-vip needs permissions to watch services, endpoints, configmaps, and manage leader election leases. This command outputs the minimum required ServiceAccount, Role (or ClusterRole), and the corresponding binding.
Flags:
--role : If true, generates a namespaced Role instead of a ClusterRole. The namespace is taken from the root --namespace flag (default: kube-system).
--rolebinding : If true, generates a RoleBinding (if --role is also true). If --role is false, a ClusterRoleBinding is generated automatically.
The output is a multi-document YAML (separated by '---'). It is safe to apply directly:
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Interface,"interface","","Name of the interface to bind to")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ServicesInterface,"serviceInterface","","Name of the interface to bind to (for services)")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.AllowInterfaceNotUp,"allowInterfaceNotUp",false,"Allow kube-vip to start even if the interface is not up")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.VIP,"vip","","The Virtual IP address")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.VIPSubnet,"vipSubnet","","The Virtual IP address subnet e.g. /32 /24 /8 etc.. (Default to 32 for IPv4 and 128 for IPv6)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.NodeName,"nodeName","","Name to be used for lease holder. Must be unique for each node/instance")
// VIP flags
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Address,"address","","an address (IP or DNS name) to use as a VIP")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.Port,"port",6443,"listen port for the VIP")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.VIPCIDR,"cidr","32","The CIDR range for the virtual IP address")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableARP,"arp",false,"Enable Arp for Vip changes")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Annotations,"annotations","","Set Node annotations prefix for parsing")
kubeVipCmd.PersistentFlags().Uint16Var(&initConfig.Port,"port",6443,"Port for the VIP")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableARP,"arp",false,"Enable Arp for VIP changes")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableWireguard,"wireguard",false,"Enable Wireguard for services VIPs")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableRoutingTable,"table",false,"Enable Routing Table for services VIPs")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.PreserveVIPOnLeadershipLoss,"preserveVipOnLeadershipLoss",false,"Preserve ARP VIP addresses on interface when leadership is lost (default: false for backward compatibility)")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.LoseLeadership,"loseLeadership",false,"Lose leadership when VIP interface goes down")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.LoseLeadershipTimeoutSeconds,"loseLeadershiptTimeoutSeconds",30,"Timeout before re-electing a leader when the VIP interface is down")
// LoadBalancer flags
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableLoadBalancer,"enableLoadBalancer",false,"enable loadbalancing on the VIP with IPVS")
kubeVipCmd.PersistentFlags().Uint16Var(&initConfig.LoadBalancerPort,"lbPort",6443,"loadbalancer port for the VIP")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.DDNS,"ddns",false,"use Dynamic DNS + DHCP to allocate VIP for address")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.MirrorDestInterface,"mirrorDestInterface","","network interface where all traffic that traverses the service interface will be mirrored to. Source interface will use default interface is servicesInterface is not set.")
// Clustering type (leaderElection)
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableLeaderElection,"leaderElection",false,"Use the Kubernetes leader election mechanism for clustering")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.LeaseDuration,"leaseDuration",5,"Length of time a Kubernetes leader lease can be held for")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RenewDeadline,"leaseRenewDuration",3,"Length of time a Kubernetes leader can attempt to renew its lease")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RetryPeriod,"leaseRetry",1,"Number of times the host will retry to hold a lease")
// Clustering type (raft)
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.StartAsLeader,"startAsLeader",false,"Start this instance as the cluster leader")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.AddPeersAsBackends,"addPeersToLB",true,"Add raft peers to the load-balancer")
// Packet flags
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableMetal,"metal",false,"This will use the Equinix Metal API (requires the token ENV) to update the EIP <-> VIP")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.MetalAPIKey,"metalKey","","The API token for authenticating with the Equinix Metal API")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.MetalProject,"metalProject","","The name of project already created within Equinix Metal")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.MetalProjectID,"metalProjectID","","The ID of project already created within Equinix Metal")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ProviderConfig,"provider-config","","The path to a provider configuration")
// Load Balancer flags
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableLoadBalancer,"lbEnable",false,"Enable a load-balancer on the VIP")
kubeVipCmd.PersistentFlags().BoolVar(&initLoadBalancer.BindToVip,"lbBindToVip",true,"Bind example load balancer to VIP")
kubeVipCmd.PersistentFlags().StringVar(&initLoadBalancer.Type,"lbType","tcp","Type of load balancer instance (TCP/HTTP)")
kubeVipCmd.PersistentFlags().StringVar(&initLoadBalancer.Name,"lbName","Kubeadm Load Balancer","The name of a load balancer instance")
kubeVipCmd.PersistentFlags().IntVar(&initLoadBalancer.Port,"lbPort",6443,"Port that load balancer will expose on")
kubeVipCmd.PersistentFlags().IntVar(&initLoadBalancer.BackendPort,"lbBackEndPort",6444,"A port that all backends may be using (optional)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.LeaderElectionType,"leaderElectionType","kubernetes","Defines the backend to run the leader election: kubernetes or etcd. Defaults to kubernetes.")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.LeaseName,"leaseName","plndr-cp-lock","Name of the lease that is used for leader election")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.LeaseDuration,"leaseDuration",15,"Length of time (in seconds) a Kubernetes leader lease can be held for")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RenewDeadline,"leaseRenewDuration",10,"Length of time (in seconds) a Kubernetes leader can attempt to renew its lease")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RetryPeriod,"leaseRetry",2,"Length of time (in seconds) the LeaderElector clients should wait between tries of actions")
// BGP flags
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableBGP,"bgp",false,"This will enable BGP support within kube-vip")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.BGPAttachIPToInterface,"bgpAttachIPToInterface",false,"Assign BGP service VIPs to the configured interface")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPConfig.RouterID,"bgpRouterID","","The routerID for the bgp server")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPConfig.SourceIF,"sourceIF","","The source interface for bgp peering (not to be used with sourceIP)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPConfig.SourceIP,"sourceIP","","The source address for bgp peering (not to be used with sourceIF)")
kubeVipCmd.PersistentFlags().Uint32Var(&initConfig.BGPConfig.AS,"localAS",65000,"The local AS number for the bgp server")
kubeVipCmd.PersistentFlags().Uint64Var(&initConfig.BGPConfig.HoldTime,"bgpHoldTimer",30,"The hold timer for all bgp peers (it defines the time a session is held)")
kubeVipCmd.PersistentFlags().Uint64Var(&initConfig.BGPConfig.KeepaliveInterval,"bgpKeepAliveInterval",10,"The keepalive interval for all bgp peers (it defines the heartbeat of keepalive messages)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPPeerConfig.Address,"peerAddress","","The address of a BGP peer")
kubeVipCmd.PersistentFlags().Uint32Var(&initConfig.BGPPeerConfig.AS,"peerAS",65000,"The AS number for a BGP peer")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPPeerConfig.Password,"peerPass","","The md5 password for a BGP peer")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.BGPPeerConfig.MultiHop,"multihop",false,"This will enable BGP multihop support")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Annotations,"annotations","","Set Node annotations prefix for parsing")
// Control plane specific flags
kubeVipCmd.PersistentFlags().StringVarP(&initConfig.Namespace,"namespace","n","kube-system","The configuration map defined within the cluster")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.BGPConfig.Zebra.Enabled,"zebra",false,"This will enable Zebra support within kube-vip")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPConfig.Zebra.URL,"zebraUrl","unix:/var/run/frr/zserv.api","Path to the unix domain socket for connecting to Zebra daemon")
kubeVipCmd.PersistentFlags().Uint32Var(&initConfig.BGPConfig.Zebra.Version,"zebraVersion",6,"Zebra API Version")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.BGPConfig.Zebra.SoftwareName,"zebraSoftwareName","frr8.3","Software Name for Zebra")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ControlPlaneHealthCheck.Address,"controlPlaneHealthCheckAddress","","URL to poll for the control-plane health check when using BGP without leader election")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.ControlPlaneHealthCheck.PeriodSeconds,"controlPlaneHealthCheckPeriodSeconds",5,"Seconds between control-plane health checks")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.ControlPlaneHealthCheck.TimeoutSeconds,"controlPlaneHealthCheckTimeoutSeconds",3,"Timeout for each control-plane health check request")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.ControlPlaneHealthCheck.FailureThreshold,"controlPlaneHealthCheckFailureThreshold",3,"Consecutive control-plane health check failures before withdrawing the BGP route")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ControlPlaneHealthCheck.CAPath,"controlPlaneHealthCheckCAPath","","Path to CA certificate for TLS verification when the control-plane health check URL is HTTPS")
// Namespace for kube-vip
kubeVipCmd.PersistentFlags().StringVarP(&initConfig.Namespace,"namespace","n","kube-system","The namespace for the configmap defined within the cluster")
// Manage logging
kubeVipCmd.PersistentFlags().Uint32Var(&logLevel,"log",4,"Set the level of logging")
kubeVipCmd.PersistentFlags().Int32Var(&initConfig.Logging,"log",0,"Set the level of logging")
// Service flags
kubeVipService.Flags().StringVarP(&configMap,"configMap","c","plndr","The configuration map defined within the cluster")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableControlPane,"controlplane",false,"Enable HA for control plane, hybrid mode")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RoutingTableID,"tableID",198,"The routing table used for all table entries")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RoutingTableType,"tableType",unix.RTN_UNICAST,"The type of route that will be added to the routing table")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.RoutingProtocol,"routingProtocol",248,"The routing protocol value used to create routes")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.CleanRoutingTable,"cleanRoutingTable",false,"Clean routing table of redundant routes on start")
// Behaviour flags
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableControlPlane,"controlplane",false,"Enable HA for control plane")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.DetectControlPlane,"autodetectcp",false,"Determine working address for control plane (from loopback)")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableServicesElection,"servicesElection",false,"Enable leader election per kubernetes service")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.LoadBalancerClassOnly,"lbClassOnly",false,fmt.Sprintf("Enable load balancing only for services with LoadBalancerClass %q",kubevip.LBClassName))
kubeVipCmd.PersistentFlags().StringVar(&initConfig.LoadBalancerClassName,"lbClassName",kubevip.LBClassName,fmt.Sprintf("Name of load balancer class for kube-VIP, defaults to %q",kubevip.LBClassName))
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.LoadBalancerClassLegacyHandling,"lbClassNameLegacyHandling",true,"Use legacy LoadBalancer class name handling (e.g. accepting services both with empty and non-empty class)")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableServiceSecurity,"onlyAllowTrafficServicePorts",false,"Only allow traffic to service ports, others will be dropped, defaults to false")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableNodeLabeling,"enableNodeLabeling",false,fmt.Sprintf("Enable leader node labeling with %q, defaults to false",kubevip.HasIP))
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ServicesLeaseName,"servicesLeaseName","plndr-svcs-lock","Name of the lease that is used for leader election for services (in arp mode)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.DNSMode,"dnsMode","first","Name of the mode that DNS lookup will be performed (first, ipv4, ipv6, dual)")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.DHCPMode,"dhcpMode","","Mode DHCP resolving will use to obtain IP addresses (ipv4, ipv6, dual)")
fmt.Sprintf("number of times DHCP client will try to obtain an IP address (defaults to: %d, 0 for unlimited retries)",kubevip.DefaultDHCPBackoffAttempts))
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.DisableServiceUpdates,"disableServiceUpdates",false,"If true, kube-vip will process services as usual, but will not update service's Status.LoadBalancer.Ingress slice")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.EnableEndpoints,"enableEndpoints",false,"If enabled, kube-vip will only advertise services, but will use the (deprecated since v1.33) endpoints for IP addresses")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.LoInterfaceGlobalScope,"loInterfaceGlobalScope",false,"If true, kube-vip will set global scope when using the lo interface, otherwise a host scope will be used by default")
kubeVipCmd.PersistentFlags().IntVar(&initConfig.HealthCheckPort,"healthCheckPort",0,"If set to non-zero (> 1024), then this is the port that the healthcheck will listen on")
"Configures the time that the event debouncer will wait for the events arrival (default 0s - debouncer disabled, enable with min. 200ms)")
// Prometheus HTTP Server
kubeVipCmd.PersistentFlags().StringVar(&initConfig.PrometheusHTTPServer,"promethuesHTTPServer",":2112","Host and port used to expose Promethues metrics via an HTTP server")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.PrometheusHTTPServer,"prometheusHTTPServer",":2112","Host and port used to expose Prometheus metrics via an HTTP server")
// Etcd
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Etcd.CAFile,"etcdCACert","","Verify certificates of TLS-enabled secure servers using this CA bundle file")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Etcd.ClientCertFile,"etcdCert","","Identify secure client using this TLS certificate file")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.Etcd.ClientKeyFile,"etcdKey","","Identify secure client using this TLS key file")
kubeVipCmd.PersistentFlags().StringSliceVar(&initConfig.Etcd.Endpoints,"etcdEndpoints",nil,"Etcd member endpoints")
// Kubernetes client specific flags
kubeVipCmd.PersistentFlags().StringVar(&initConfig.K8sConfigFile,"k8sConfigPath","/etc/kubernetes/admin.conf","Path to the configuration file used with the Kubernetes client")
// Configuration file flag
kubeVipCmd.PersistentFlags().StringVar(&initConfig.ConfigFile,"config-file","","Path to a JSON/YAML configuration file to load settings from")
kubeVipCmd.PersistentFlags().StringVar(&initConfig.InstanceName,"instanceName","","Unique name for this kube-vip instance (currently used to isolate nftables egress tables)")
kubeVipCmd.PersistentFlags().BoolVar(&initConfig.PerServiceElectionOnDemand,"perServiceElectionOnDemand",false,"Allow kube-vip to use per-service election for annotated services")
kubeVipCmd.AddCommand(kubeKubeadm)
kubeVipCmd.AddCommand(kubeManifest)
kubeVipCmd.AddCommand(kubeVipManager)
kubeVipCmd.AddCommand(kubeVipSample)
kubeVipCmd.AddCommand(kubeVipService)
kubeVipCmd.AddCommand(kubeVipStart)
kubeVipCmd.AddCommand(kubeVipVersion)
// Sample commands
kubeVipSample.AddCommand(kubeVipSampleConfig)
kubeVipSample.AddCommand(kubeVipSampleManifest)
// Set the logging level for all subsequent functions
This contains some example code to determine how long "failovers" are taking within kube-vip, the server component should live within the cluster and the client should be externally.
## Deploy the server
Simply apply the manifest to a working cluster that has kube-vip deployed:
```
kubectl apply -f ./demo/server/deploy.yaml
```
Retrieve the loadBalancer IP that is fronting the service:
From elsewhere, clone the kube-vip repository and connect the client to the server endpoint (loadBalancer IP) with the following command:
```
go run ./demo/client/main.go -address=<vip>
```
You will only see output when the client has reconcilled the connection to a pod beneath the service, where it will print the timestamp to reconnection along with the time in milliseconds it took:
```
15:58:35.916952 3008
15:58:45.947506 2005
15:58:57.983151 3007
15:59:08.013450 2005
15:59:20.046491 3008
15:59:30.076341 2507
15:59:42.110747 3008
```
## Kill some pods to test
On a machine or control plane that has `kubectl` and has the credentials to speak to the cluster we will run a command to find the demo pod and kill it every 10 seconds:
`while true ; do kubectl delete pod $(kubectl get pods | grep -v NAME | grep vip| awk '{ print $1 }'); sleep 10; done`
This section covers two parts of the architecture:
1. The technical capabilities of `kube-vip`
2. The components to build a load-balancing service within [Kubernetes](https://kubernetes.io)
The `kube-vip` project is designed to provide both a highly available networking endpoint and load-balancing functionality for underlying networking services. The project was originally designed for the purpose of providing a resilient control-plane for Kubernetes, it has since expanded to provide the same functionality for applications within a Kubernetes cluster.
Additionally `kube-vip` is designed to be lightweight and **multi-architecture**, all of the components are built for Linux but are also built for both `x86` and `armv7`,`armhvf`,`ppc64le`. This means that `kube-vip` will run fine in **bare-metal**, **virtual** and **edge** (raspberry pi or small arm SoC devices).
## Technologies
There are a number of technologies or functional design choices that provide high-availability or networking functions as part of a VIP/Load-balancing solution.
### Cluster
The `kube-vip` service builds a multi-node or multi-pod cluster to provide High-Availability. In ARP mode a leader is elected, this node will inherit the Virtual IP and become the leader of the load-balancing within the cluster, whereas with BGP all nodes will advertise the VIP address.
When using ARP or layer2 it will use [leader election](https://godoc.org/k8s.io/client-go/tools/leaderelection)
It is also possible to use [raft](https://en.wikipedia.org/wiki/Raft_(computer_science) clustering technology, but this approach has largely been superseded by leader election especially when running in cluster.
### Virtual IP
The leader within the cluster will assume the **vip** and will have it bound to the selected interface that is declared within the configuration. When the leader changes it will evacuate the **vip** first or in failure scenarios the **vip** will be directly assumed by the next elected leader.
When the **vip** moves from one host to another any host that has been using the **vip** will retain the previous `vip <-> MAC address` mapping until the ARP (Address resolution protocol) expires the old entry (typically 30 seconds) and retrieves a new `vip <-> MAC` mapping. This can be improved using Gratuitous ARP broadcasts (when enabled), this is detailed below.
### ARP
(Optional) The `kube-vip` can be configured to broadcast a [gratuitous arp](https://wiki.wireshark.org/Gratuitous_ARP) that will typically immediately notify all local hosts that the `vip <-> MAC` has changed.
**Below** we can see that the failover is typically done within a few seconds as the ARP broadcast is recieved.
```
64 bytes from 192.168.0.75: icmp_seq=146 ttl=64 time=0.258 ms
64 bytes from 192.168.0.75: icmp_seq=147 ttl=64 time=0.240 ms
92 bytes from 192.168.0.70: Redirect Host(New addr: 192.168.0.75)
64 bytes from 192.168.0.75: icmp_seq=151 ttl=64 time=0.245 ms
```
### Load Balancing
Within a Kubernetes cluster, the load-balancing is managed by the `plndr-cloud-provider` which watches all service that are created, and for those of `type=LoadBalancer` will create the configuration for `kube-vip` to consume.
#### Load Balancing (Inside a cluster)
When using `type=LoadBalancer` within a Kubernetes cluster `kube-vip` will assign the VIP to the leader (when using ARP) or to all running Pods (when using BGP). When traffic is directed to a node with the VIP then the rules configured by `kube-proxy` will redirect the traffic to one of the pods running in the service.
#### Load Balancing (Outside a cluster)
Within the configuration of `kube-vip` multiple load-balancers can be created, below is the example load-balancer for a Kubernetes Control-plane:
```
loadBalancers:
- name: Kubernetes Control Plane
type: tcp
port: 6443
bindToVip: true
backends:
- port: 6444
address: 192.168.0.70
- port: 6444
address: 192.168.0.71
- port: 6444
address: 192.168.0.72
```
The above load balancer will create an instance that listens on port `6443` and will forward traffic to the array of backend addresses. If the load-balancer type is `tcp` then the backends will be IP addresses, however if the backend is set to `http` then the backends should be URLs:
```
type: http
port: 6443
bindToVip: true
backends:
- port: 6444
address: https://192.168.0.70
```
Additionally the load-balancing within `kibe-vip` has two modes of operation:
`bindToVip: false` - will result in every node in the cluster binding all load-balancer port(s) to all interfaces on the host itself
`bindToVip: true` - The load-balancer will only **bind** to the VIP address.
## Components within a Kubernetes Cluster
The `kube-vip` kubernetes load-balancer requires a number of components in order to function:
- The Plunder Cloud Provider -> [https://github.com/kube-vip/plndr-cloud-provider](https://github.com/kube-vip/plndr-cloud-provider)
- The Kube-Vip Deployment -> [https://github.com/kube-vip/kube-vip](https://github.com/kube-vip/kube-vip)
The cloud provider works like all Kubernetes cloud providers and is built using the Kubernetes cloud-provider SDK. It's role is to provide the same cloud "like" services one would expect from services such as AWS / Azure / GCP etc.. in that when a user requests functionality then the cloud provider can speak natively to the underlying vendor and provision the required service
e.g. _In AWS when requesting a Kubernetes LoadBalancer, the cloud provider will provision an **ELB**_
The `Plunder cloud Provider` is *currently* only designed to intercept the creation of LoadBalancers and translate that into a `kube-vip` load balancer.
It is configured by a `configMap` within the `kube-system` namespace that contains the ranges of addresses that the other `kube-vip` load-balancers can use, it will also manage the allocation of addresses and then build the configMap configurations in these namespaces for consumption by `kube-vip`. The IP addresses for each namespace should be in the structure `cidr-<namespace>` followed by the cidr range for the address pool.
# Load Balancing a Kubernetes Cluster (Control-Plane) (pre 0.1.5)
This document covers all of the details for using `kube-vip` to build a HA Kubernetes cluster
`tl;dr version`
- Generate/modify first node `kube-vip` config/manifest
-`init` first node
-`join` remaining nodes
- Add remaining config/manifests
## Infrastructure architecture
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.75 |
| controlPlane01 | 10.0.0.70 |
| controlPlane02 | 10.0.0.71 |
| controlPlane03 | 10.0.0.72 |
All nodes are running Ubuntu 18.04, Docker CE and will use Kubernetes 1.17.0.
### Generate the `kube-vip` configuration
Make sure that the config directory exists: `sudo mkdir -p /etc/kube-vip/`, this directory can be any directory however the `hostPath` in the manifest will need modifying to point to the correct path.
```
sudo docker run -it --rm plndr/kube-vip:0.1 /kube-vip sample config | sudo tee /etc/kube-vip/config.yaml
```
### Modify the configuration
**Cluster Configuration**
Modify the `remotePeers` to point to the correct addresses of the other two nodes, ensure that their `id` is unique otherwise this will confuse the raft algorithm. The `localPeer` should be the configuration of the current node (`controlPlane01`), which is where this instance of the cluster will run.
As this node will be the first node, it will need to elect itself leader as until this occurs the VIP won’t be activated!
`startAsLeader: true`
**VIP Config**
We will need to set our VIP address to `192.168.0.75` and to ensure all hosts are updated when the VIP moves we will enable ARP broadcasts `gratuitousARP: true`
**Load Balancer**
We will configure the load balancer to sit on the standard API-Server port `6443` and we will configure the backends to point to the API-servers that will be configured to run on port `6444`. Also for the Kubernetes Control Plane we will configure the load balancer to be of `type: tcp`.
We can also use `6443` for both the VIP and the API-Servers, in order to do this we need to specify that the api-server is bound to it's local IP. To do this we use the `--apiserver-advertise-address` flag as part of the `init`, this means that we can then bind the same port to the VIP and we wont have a port conflict.
To generate the basic Kubernetes static pod `yaml` configuration:
Make sure that the manifest directory exists: `sudo mkdir -p /etc/kubernetes/manifests/`
```
sudo docker run -it --rm plndr/kube-vip:0.1 /kube-vip sample manifest | sudo tee /etc/kubernetes/manifests/kube-vip.yaml
```
Ensure that `image: plndr/kube-vip:<x>` is modified to point to a specific version (`0.1` at the time of writing), refer to [docker hub](https://hub.docker.com/r/plndr/kube-vip/tags) for details. Also ensure that the `hostPath` points to the correct `kube-vip` configuration, if it isn’t the above path.
The **vip** is set to `192.168.0.75` and this first node will elect itself as leader, and as part of the `kubeadm init` it will use the VIP in order to speak back to the initialising api-server.
We first will need to create the `kube-vip` configuration that resides in `/etc/kube-vip/config.yaml` or we can regenerate it from scratch using the above example. Ensure that the configuration is almost identical with the `localPeer` and `remotePeers` sections are updated for each node. Finally, ensure that the remaining nodes will behave as standard cluster nodes by setting `startAsLeader: false`.
At this point **DON’T** generate the manifests, this is due to some bizarre `kubeadm/kubelet` behaviour.
```
kubeadm join 192.168.0.75:6443 --token <tkn> \
--discovery-token-ca-cert-hash sha256:<hash> \
--control-plane --certificate-key <key>
```
**After** this node has been added to the cluster, we can add the manifest to also add this node as a `kube-vip` member. (Adding the manifest afterwards doesn’t interfere with `kubeadm`).
```
sudo docker run -it --rm plndr/kube-vip:0.1 /kube-vip sample manifest | sudo tee /etc/kubernetes/manifests/kube-vip.yaml
```
Once this node is added we will be able to see that the `kube-vip` pod is up and running as expected:
```
user@controlPlane01:~$ kubectl get pods -A | grep vip
# Load Balancing a Kubernetes Cluster (Control-Plane)
This document covers the newer (post `0.1.5`) method for using `kube-vip` to provide HA for a Kubernetes Cluster. The documentation for older releases can be found [here](./0.1.4/)
This document covers all of the details for using `kube-vip` to build a HA Kubernetes cluster
`tl;dr version`
- Generate/modify first node `kube-vip` config/manifest
-`init` first node
-`join` remaining nodes
- Add remaining config/manifests
Below are examples of the steps required:
```
# First Node
sudo docker run --network host --rm plndr/kube-vip:0.1.5 kubeadm init --interface ens192 --vip 192.168.0.81 --startAsLeader=true | sudo tee /etc/kubernetes/manifests/vip.yaml
sudo docker run -v /etc/kubernetes/admin.conf:/etc/kubernetes/admin.conf --network host --rm plndr/kube-vip:0.1.5 kubeadm join --interface ens192 --vip 192.168.0.81 --startAsLeader=false | sudo tee /etc/kubernetes/manifests/vip.yaml
```
## Infrastructure architecture
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.75 |
| controlPlane01 | 10.0.0.70 |
| controlPlane02 | 10.0.0.71 |
| controlPlane03 | 10.0.0.72 |
All nodes are running Ubuntu 18.04, Docker CE and will use Kubernetes 1.17.0.
### Generate the `kube-vip` configuration
Kube-Vip no longer requires storing it's configuration in a seperate directory and will now store its configuration in the actual manifest that defines the static pods.
```
sudo docker run --network host \
--rm plndr/kube-vip:0.1.5 \
kubeadm init \
--interface ens192 \
--vip 192.168.0.75 \
--startAsLeader=true | sudo tee /etc/kubernetes/manifests/vip.yaml
```
The above command will "initialise" the manifest within the `/etc/kubernetes/manifests` directory, that will be started when we actually initialise our Kubernetes cluster with `kubeadm init`
### Modify the configuration
**Cluster Configuration**
As this node will be the first node, it will need to elect itself leader as until this occurs the VIP won’t be activated!
`--startAsLeader=true`
**VIP Config**
We will need to set our VIP address to `192.168.0.75` with `--vip 192.168.0.75` and to ensure all hosts are updated when the VIP moves we will enable ARP broadcasts `--arp` (defaults to `true`)
**Load Balancer**
We will configure the load balancer to sit on the standard API-Server port `6443` and we will configure the backends to point to the API-servers that will be configured to run on port `6444`. Also for the Kubernetes Control Plane we will configure the load balancer to be of `type: tcp`.
We can also use `6443` for both the VIP and the API-Servers, in order to do this we need to specify that the api-server is bound to it's local IP. To do this we use the `--apiserver-advertise-address` flag as part of the `init`, this means that we can then bind the same port to the VIP and we wont have a port conflict.
**vip.yaml** Static-pod Manifest
`$ sudo cat /etc/kubernetes/manifests/vip.yaml`
```
apiVersion: v1
kind: Pod
metadata:
creationTimestamp: null
name: kube-vip
namespace: kube-system
spec:
containers:
- args:
- start
env:
- name: vip_arp
value: "true"
- name: vip_interface
value: ens192
- name: vip_address
value: 192.168.0.81
- name: vip_startleader
value: "true"
- name: vip_addpeerstolb
value: "true"
- name: vip_localpeer
value: controlPlane01:192.168.0.70:10000
- name: lb_backendport
value: "6443"
- name: lb_name
value: Kubeadm Load Balancer
- name: lb_type
value: tcp
- name: lb_bindtovip
value: "true"
image: plndr/kube-vip:0.1.5
imagePullPolicy: Always
name: kube-vip
resources: {}
securityContext:
capabilities:
add:
- NET_ADMIN
- SYS_TIME
hostNetwork: true
status: {}
```
### First Node
To generate the basic Kubernetes static pod `yaml` configuration:
Make sure that the manifest directory exists: `sudo mkdir -p /etc/kubernetes/manifests/`
```
sudo docker run --network host \
--rm plndr/kube-vip:0.1.5 \
kubeadm init \
--interface ens192 \
--vip 192.168.0.75 \
--startAsLeader=true | sudo tee /etc/kubernetes/manifests/vip.yaml
```
Ensure that `image: plndr/kube-vip:<x>` is modified to point to a specific version (`0.1.5` at the time of writing), refer to [docker hub](https://hub.docker.com/r/plndr/kube-vip/tags) for details.
The **vip** is set to `192.168.0.75` and this first node will elect itself as leader, and as part of the `kubeadm init` it will use the VIP in order to speak back to the initialising api-server.
At this point **DON’T** generate the manifests, this is due to some bizarre `kubeadm/kubelet` behaviour.
```
kubeadm join 192.168.0.75:6443 --token <tkn> \
--discovery-token-ca-cert-hash sha256:<hash> \
--control-plane --certificate-key <key>
```
**After** this node has been added to the cluster, we can add the manifest to also add this node as a `kube-vip` member. (Adding the manifest afterwards doesn’t interfere with `kubeadm`).
# Load Balancing a Kubernetes Cluster (Control-Plane)
**Note**: The most common deployment currently for HA Kubernetes clusters w/`kube-vip` involved `kubeadm`, however recently we've worked to bring a method of bringing `kube-vip` to other types of Kubernetes cluster. Typically this deployment method makes use of a daemonset that is usually brought up during the cluster instantiation.. So for those wanting to deploy [k3s](https://k3s.io), we now have installation steps available [here](https://kube-vip.io/control-plane/#k3s),
This document covers the newer (post `0.1.6`) method for using `kube-vip` to provide HA for a Kubernetes Cluster. The documentation for older releases can be found [here](./0.1.5/)
From version `0.1.6` we've moved `kube-vip` from raft to leaderElection within the Kubernetes cluster. After a lot of testing it became clear that the leaderElection gave quicker reconciliation when removing nodes etc.. during upgrades and failures.
For **more** configuration around LeaderElection click [here](https://kube-vip.io/control-plane/#leaderelection-configuration).
This document covers all of the details for using `kube-vip` to build a HA Kubernetes cluster
`tl;dr version`
- Generate/modify first node `kube-vip` config/manifest
-`init` first node
-`join` remaining nodes
- Add remaining config/manifests
Below are examples of the steps required:
```
# First Node
sudo docker run --network host --rm plndr/kube-vip:0.2.1 manifest pod \
--interface ens192 \
--vip 192.168.0.75 \
--arp \
--leaderElection | sudo tee /etc/kubernetes/manifests/vip.yaml
sudo docker run --network host --rm plndr/kube-vip:0.2.1 manifest pod \
--interface ens192 \
--vip 192.168.0.75 \
--arp \
--leaderElection | sudo tee /etc/kubernetes/manifests/vip.yaml
```
## Infrastructure architecture
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.75 |
| controlPlane01 | 10.0.0.70 |
| controlPlane02 | 10.0.0.71 |
| controlPlane03 | 10.0.0.72 |
All nodes are running Ubuntu 18.04, Docker CE and will use Kubernetes 1.17.0.
### Generate the `kube-vip` configuration
`kube-vip` no longer requires storing its configuration in a separate directory and will now store its configuration in the actual manifest that defines the static pods.
```
sudo docker run --network host \
--rm plndr/kube-vip:0.2.1 \
manifest pod \
--interface ens192 \
--vip 192.168.0.75 \
--arp \
--leaderElection | sudo tee /etc/kubernetes/manifests/vip.yaml
```
The above command will "initialise" the manifest within the `/etc/kubernetes/manifests` directory, that will be started when we actually initialise our Kubernetes cluster with `kubeadm init`
### Modify the configuration
**Cluster Configuration**
To enable Kubernetes leader Election passing the `--leaderElection` flag will enable `kube-vip` to use the Kubernetes leaderElection functionality to work out which member is the leader.
**VIP Config**
We will need to set our VIP address to `192.168.0.75` with `--vip 192.168.0.75` and to ensure all hosts are updated when the VIP moves we will enable ARP broadcasts `--arp` (defaults to `true`)
**vip.yaml** Static-pod Manifest
`$ sudo cat /etc/kubernetes/manifests/vip.yaml`
```
apiVersion: v1
kind: Pod
metadata:
creationTimestamp: null
name: kube-vip
namespace: kube-system
spec:
containers:
- args:
- start
env:
- name: vip_arp
value: "true"
- name: vip_interface
value: ens160
- name: vip_leaderelection
value: "true"
- name: vip_leaseduration
value: "5"
- name: vip_renewdeadline
value: "3"
- name: vip_retryperiod
value: "1"
- name: vip_address
value: 192.168.0.75
image: plndr/kube-vip:0.2.1
imagePullPolicy: Always
name: kube-vip
resources: {}
securityContext:
capabilities:
add:
- NET_ADMIN
- SYS_TIME
hostNetwork: true
status: {}
```
### First Node
To generate the basic Kubernetes static pod `yaml` configuration:
Make sure that the manifest directory exists: `sudo mkdir -p /etc/kubernetes/manifests/`
```
sudo docker run --network host \
--rm plndr/kube-vip:0.2.1 \
manifest pod \
--interface ens192 \
--vip 192.168.0.75 \
--arp \
--leaderElection | sudo tee /etc/kubernetes/manifests/vip.yaml
```
Ensure that `image: plndr/kube-vip:<x>` is modified to point to a specific version (`0.1.8` at the time of writing), refer to [docker hub](https://hub.docker.com/r/plndr/kube-vip/tags) for details.
The **vip** is set to `192.168.0.75` and this first node will elect itself as leader, and as part of the `kubeadm init` it will use the VIP in order to speak back to the initialising api-server.
At this point **DON’T** generate the manifests, this is due to some bizarre `kubeadm/kubelet` behaviour.
```
kubeadm join 192.168.0.75:6443 --token <tkn> \
--discovery-token-ca-cert-hash sha256:<hash> \
--control-plane --certificate-key <key>
```
**After** this node has been added to the cluster, we can add the manifest to also add this node as a `kube-vip` member. (Adding the manifest afterwards doesn’t interfere with `kubeadm`).
```
sudo docker run --network host \
--rm plndr/kube-vip:0.2.1 \
manifest pod \
--interface ens192 \
--vip 192.168.0.75 \
--arp \
--leaderElection | sudo tee /etc/kubernetes/manifests/vip.yaml
```
Once this node is added we will be able to see that the `kube-vip` pod is up and running as expected:
```
user@controlPlane01:~$ kubectl get pods -A | grep vip
A new flag `--address` is introduced to support using a DNS record as the control plane endpoint. `kube-vip` will do a dns lookup to retrieve the IP for the DNS record, and use that IP as the VIP. An `dnsUpdater` periodically checks and updates the system if IP changes for the DNS record.
### Dynamic DNS Support (added in 0.2.1)
`kube-vip` was also updated to support DHCP + [Dynamic DNS](https://en.wikipedia.org/wiki/Dynamic_DNS), for the use case where it's not able to reserve a static IP for the control plane endpoint.
A new flag `--ddns` is introduced. Once enabled, `kube-vip` expects the input `--address` will be a FQDN without binding to an IP. Then `kube-vip` will start a dhcp client to allocate an IP for the hostname of FQDN, and maintain the lease for it.
Once DHCP returns an IP for the FQDN, the same `dnsUpdater` runs to periodically checks and updates if IP got changed.
## BGP Support (added in 0.1.8)
In version `0.1.8`+ `kube-vip` was updated to support [BGP](https://en.wikipedia.org/wiki/Border_Gateway_Protocol) as a VIP failover mechanism. When a node is elected as a leader then it will update it's peers so that they are aware to route traffic to that node in order to access the VIP.
The following new flags are used:
- `--bgp` This will enable BGP support within kube-vip
- `--localAS` The local AS number
- `--bgpRouterID` The local router address
- `--peerAS` The AS number for a BGP peer
- `--peerAddress` The address of a BGP peer
### BGP Packet support
If the `--bgp` flag is passed alone with the Packet flags `packet, packetKey and packetProject`, then the Packet API will be used in order to determine the BGP configuration for the nodes being used in the cluster. This automates a lot of the process and makes using BGP within Packet much simpler.
## Packet Support (added in 0.1.7)
Recently in version `0.1.7` of `kube-vip` we added the functionality to use a Packet Elastic IP as the virtual IP fronting the Kubernetes Control plane cluster. In order to first get out virtual IP we will need to use our Packet account and create a EIP (either public (eek) or private). We will only need a single address so a `/32` will suffice, once this is created as part of a Packet project we can now apply this address to the servers that live in the same project.
In this example we've logged into the UI can created a new EIP of `147.75.1.2`, and we've deployed three small server instances with Ubuntu.
The following new flags are used:
- `--packet` which enables the use of the Packet API
- `--packetKey` which is our API key
- `--packetProject`which is the name of our Packet project where our servers and EIP are located.
*Also* the `--arp` flag should NOT be used as it wont work within the Packet network.
### Variables
```
export EIP=1.1.1.1
export PACKET_AUTH_TOKEN=XYZ
```
### First node
```
# Generate the manifest
sudo docker run --network host --rm plndr/kube-vip:0.2.1 manifest pod \
--arp=false \
--interface lo \
--vip $EIP \
--leaderElection \
--packet \
--packetKey $PACKET_AUTH_TOKEN \
--packetProject vipTest | sudo tee /etc/kubernetes/manifests/vip.yaml\
A kubeadm join will fail as the `controlPlane01` still exists as an endpoint, so we have two options (manual steps and configmap edit to remove all mention of this node, or we can bring this node up and `kubeadm reset` the node (which we will do)).
```
$ kubectl get nodes
NAME STATUS ROLES AGE VERSION
controlplane01 NotReady master 14m v1.17.0
controlplane02 Ready master 13m v1.17.2
controlplane03 Ready master 13m v1.17.0
controlplane04 NotReady master 9s v1.17.0
```
After this we can add this node into `kube-vip` with the same manifest created by `docker run`.
## LeaderElection configuration
The Kubernetes LeaderElection that is used to manage the election of a new leader now supports having it's settings managed through flags.
- `--leaseDuration` Length of time a Kubernetes leader lease can be held for
- `--leaseRenewDuration` Length of time a Kubernetes leader can attempt to renew its lease
- `--leaseRetry` Number of times the host will retry to hold a lease
For larger clusters the `--leaseDuration` and `--leaseRenewDuration` may need extending due to slower `etcd` performance. (Tested with 2000 nodes)
## k3s
This section details the steps required to deploye `k3s` in a Highly available manner, using kube-vip deployed within k3s as a daemonset on the control plane nodes. As of `k3s` v1 the persistent datastore is back to etcd, however this guide will also include the steps for using `mysql`.
### Example MySQL deployment (optional)
To quickly validate this we can use docker on a host to quickly spin up a mysql database to store the persistent Kubernetes data.
The `kube-vip` manifest contains all the configuration for starting up `kube-vip` within the `k3s` cluster, it runs as a daemonset with affinity/taints for the control-plane nodes. As `k3s` starts it will parse all manifests in the manifests folder and start the highly available VIP across all control plane nodes in the cluster.
#### Create the `k3` manifests directory
Create the manifests directory, this directory is used by `k3s` for all of it's other deployments once it's up and running.
In Hybrid mode `kube-vip` will manage a virtual IP address that is passed through it's configuration for a Highly Available Kubernetes cluster, it will also "watch" services of `type:LoadBalancer` and once their `spec.LoadBalancerIP` is updated (typically by a cloud controller) it will advertise this address using BGP/ARP.
**Note about Daemonsets**
The "hybrid" mode is now the default mode in `kube-vip` from `0.2.3` onwards, and allows both modes to be enabled at the same time.
If the Kubernetes installer allows for adding a Virtual IP as an additional [SAN](https://en.wikipedia.org/wiki/Subject_Alternative_Name) to the API server certificate then we can apply `kube-vip` to the cluster once the first node has been brought up.
Unlike generating the static manifest there are a few more things that may need configuring, this page will cover most scenarios.
## Create the RBAC settings
As a daemonSet runs within the Kubernetes cluster it needs the correct access to be able to watch Kubernetes services and other objects. In order to do this we create a User, Role, and a binding.. we can apply this with the command:
This section only covers generating a simple *BGP* configuration, as the main focus is will be on additional changes to the manifest. For more examples we can look at [here](/hybrid/static/).
**Note:** Pay attention if using the "static" examples, as the `manifest` subcommand should use `daemonset` and NOT `pod`.
### Set configuration details
`export VIP=192.168.0.40`
`export INTERFACE=<interface>`
### Configure to use a container runtime
The easiest method to generate a manifest is using the container itself, below will create an alias for different container runtimes.
#### containerd
`alias kube-vip="ctr run --rm --net-host docker.io/plndr/kube-vip:0.3.1 vip"`
#### Docker
`alias kube-vip="docker run --network host --rm plndr/kube-vip:0.3.1"`
### BGP Example
This configuration will create a manifest that will start `kube-vip` providing **controlplane** and **services** management. **Unlike** ARP, all nodes in the BGP configuration will advertise virtual IP addresses.
**Note** we bind the address to `lo` as we don't want multiple devices that have the same address on public interfaces. We can specify all the peers in a comma seperate list in the format of `address:AS:password:multihop`.
**Note 2** we pass the `--inCluster` flag as this is running as a daemonSet within the Kubernetes cluster and therefore will have access to the token inside the running pod.
**Note 2** we pass the `--taint` flag as we're deploying `kube-vip` as both a daemonset and as advertising controlplane, we want to taint this daemonset to only run on the worker nodes.
-`nodeSelector` - Ensures that this particular daemonset only runs on control plane nodes
-`serviceAccountName: kube-vip` - this specifies the user in the `rbac` that will give us the permissions to get/update services.
-`hostNetwork: true` - This pod will need to modify interfaces (for VIPs)
-`env {...}` - We pass the configuration into the kube-vip pod through environment variables.
## Equinix Metal Overview (using the [Equinix Metal CCM](https://github.com/packethost/packet-ccm))
The below example is for running `type:LoadBalancer` services on worker nodes only and will create a daemonset that will run `kube-vip`.
**NOTE** This use-case requires the [Equinix Metal CCM](https://github.com/packethost/packet-ccm) to be installed and that the cluster/kubelet is configured to use an "external" cloud provider.
This is important as the CCM will apply the BGP configuration to the [node annotations](https://kubernetes.io/docs/concepts/overview/working-with-objects/annotations/) making it easy for `kube-vip` to find the networking configuration it needs to expose load balancer addresses. The `--annotations metal.equinix.com` will cause kube-vip to "watch" the annotations of the worker node that it is running on, once all of the configuarion has been applied by the CCM then the `kube-vip` pod is ready to advertise BGP addresses for the service.
```
kube-vip manifest daemonset \
--interface $INTERFACE \
--services \
--bgp \
--annotations metal.equinix.com \
--inCluster | k apply -f -
```
### Troubleshooting
If `kube-vip` has been sat waiting for a long time then you may need to investigate that the annotations have been applied correctly by doing running the `describe` on the node:
If there are errors regarding `169.254.255.1` or `169.254.255.2` in the `kube-vip` logs then the routes to the ToR switches that provide BGP peering may by missing from the nodes. They can be replaced with the below command:
Additionally examining the logs of the Packet CCM may reveal why the node is not yet ready.
## K3s overview (on Equinix Metal)
### Step 1: TIDY (best if something was running before)
`rm -rf /var/lib/rancher /etc/rancher ~/.kube/*; ip addr flush dev lo; ip addr add 127.0.0.1/8 dev lo; mkdir -p /var/lib/rancher/k3s/server/manifests/`
We can deploy kube-vip in two different methods, which completely depends on your use-case and method for installing Kubernetes:
- Static Pods (hybrid)
- Daemonset (hybrid, requires taint)
## **Prerequisites**
In order for `kube-vip` to be able to speak with the Kubernetes API server, we need to be able to resolve the hostname within the pod. In order to ensure this will work as expected the `/etc/hosts` file should have the `hostname` of the server within it. The `/etc/hosts` file is passed into the running container and will ensure that the pod isn't "confused" by any Kubernetes networking.
## Kubernetes Services (`type:LoadBalancer`)
To learn more about how `kube-vip` in hybrid works with the LoadBalancer services within a kubernetes cluster the documentation is [here](./services/). To get `kube-vip` deployed read on !
## Static Pods
Static pods are a Kubernetes pod that is ran by the `kubelet` on a single node, and is **not** managed by the Kubernetes cluster itself. This means that whilst the pod can appear within Kubernetes it can't make use of a variety of kubernetes functionality (such as the kubernetes token or `configMaps`). The static pod approach is primarily required for [kubeadm](https://kubernetes.io/docs/setup/production-environment/tools/kubeadm/create-cluster-kubeadm/), this is due to the sequence of actions performed by `kubeadm`. Ideally we want `kube-vip` to be part of the kubernetes cluster, for various bits of functionality we also need `kube-vip` to provide a HA virtual IP as part of the installation.
The sequence of events for this to work follows:
1. Generate a `kube-vip` manifest in the static pods manifest folder
2. Run `kubeadm init`, this generates the manifests for the control plane and wait to connect to the VIP
3. The `kubelet` will parse and execute all manifest, including the `kube-vip` manifest
4.`kube-vip` starts and advertises our VIP
5. The `kubeadm init` finishes succesfully.
## Daemonset
Other Kubernetes distributions can bring up a Kubernetes cluster, without depending on a VIP (BUT they are configured to support one). A prime example of this would be k3s, that can be configured to start and also sign the certificates to allow incoming traffic to a virtual IP. Given we don't need the VIP to exist **before** the cluster, we can bring up the k3s node(s) and then add `kube-vip` as a daemonset for all control plane nodes.
# Deploying `kube-vip`
The simplest method for generating the Kubernetes manifests is with `kube-vip` itself.. The subcommand `manifest pod|daemonset` can be used to generate specific types of Kubernetes manifests for use in a cluster. These subcommands can be configured with additional flags to enable/disable BGP/ARP/LeaderElection and a host of other options.
Both Examples will use the same Architecture:
#### Infrastructure architecture
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.40 |
| controlPlane01 | 10.0.0.41 |
| controlPlane02 | 10.0.0.42 |
| controlPlane03 | 10.0.0.43 |
| worker01 | 10.0.0.44 |
All nodes are running Ubuntu 18.04, Docker CE and will use Kubernetes 1.19.0, we only have one worker as we're going to use our controlPlanes in "hybrid" mode.
## As a static Pod (for kubeadm)
The details for creating a static pod are available [here](./static/)
## As a daemonset
When using `kube-vip` as a daemonset the details are available [here](./daemonset/)
| |`--services`|Enables `kube-vip` to watch services of type:LoadBalancer||
|**Vip Config** ||||
| |`--arp`|Enables ARP brodcasts from Leader||
| |`--bgp`|Enables BGP peering from `kube-vip`||
| |`--vip`|`<IP Address>`|(deprecated)|
| |`--address`|`<IP Address>` or `<DNS name>`||
| |`--interface`|`<linux interface>`||
| |`--leaderElection`|Enables Kubernetes LeaderElection|Used by ARP, as only the leader can broadcast|
|**Services**||||
| |`--cidr`|Defaults "32"|Used when advertising BGP addresses (typically as `x.x.x.x/32`)|
|**Kubernetes**||||
| |`--inCluster`|Defaults to looking inside the Pod for the token||
| |`--taint`|Enables a taint, stopping control plane daemonset being on workers||
|**LeaderElection**||||
| |`--leaseDuration`|default 5|Seconds a lease is held for|
| |`--leaseRenewDuration`|default 3|Seconds a leader can attempt to renew the lease|
| |`--leaseRetry`|default 1|Number of times the leader will hold the lease for|
| |`--namespace`|"kube-vip"|The namespace where the lease will reside|
|**BGP**||||
| |`--bgpRouterID`|`<IP Address>`|Typically the address of the local node|
| |`--localAS`|default 65000|The AS we peer from|
| |`--bgppeers`|`<address:AS:password:mutlihop>`|Comma seperate list of BGP peers|
| |`--peerAddress`|`<IP Address>`|Address of a single BGP Peer|
| |`--peerAS`|default 65000|AS of a single BGP Peer|
| |`--peerPass`|""| Password to work with a single BGP Peer|
| |`--multiHop`|Enables eBGP MultiHop| Enable multiHop with a single BGP Peer|
| |`--annotaions`|`<provider string>`|Startup will be paused until the node annotaions contain the BGP configuration|
|**Equinix Metal**|||(May be deprecated)|
| |`--metal`|Enables Equinix Metal API calls||
| |`--metalKey`|Equinix Metal API token||
| |`--metalProject`|Equinix Metal Project (Name)||
| |`--metalProjectID`|Equinix Metal Project (UUID)||
| |`--provider-config`|Path to the Equinix Metal provider configuration|Requires the Equinix Metal CCM|
## Changelog
### Static DNS Support (added in 0.2.0)
A new flag `--address` is introduced to support using a DNS record as the control plane endpoint. `kube-vip` will do a dns lookup to retrieve the IP for the DNS record, and use that IP as the VIP. An `dnsUpdater` periodically checks and updates the system if IP changes for the DNS record.
### Dynamic DNS Support (added in 0.2.1)
`kube-vip` was also updated to support DHCP + [Dynamic DNS](https://en.wikipedia.org/wiki/Dynamic_DNS), for the use case where it's not able to reserve a static IP for the control plane endpoint.
A new flag `--ddns` is introduced. Once enabled, `kube-vip` expects the input `--address` will be a FQDN without binding to an IP. Then `kube-vip` will start a dhcp client to allocate an IP for the hostname of FQDN, and maintain the lease for it.
Once DHCP returns an IP for the FQDN, the same `dnsUpdater` runs to periodically checks and updates if IP got changed.
## BGP Support (added in 0.1.8)
In version `0.1.8``kube-vip` was updated to support [BGP](https://en.wikipedia.org/wiki/Border_Gateway_Protocol) as a VIP failover mechanism. When a node is elected as a leader then it will update it's peers so that they are aware to route traffic to that node in order to access the VIP.
The following new flags are used:
-`--bgp` This will enable BGP support within kube-vip
-`--localAS` The local AS number
-`--bgpRouterID` The local router address
-`--peerAS` The AS number for a BGP peer
-`--peerAddress` The address of a BGP peer
### Equinix Metal BGP support
If the `--bgp` flag is passed along with the Equinix Metal flags `metal, metalKey and metalProject`, then Equinix Metal API will be used in order to determine the BGP configuration for the nodes being used in the cluster. This automates a lot of the process and makes using BGP within Equinix Metal much simpler.
## Equinix Metal Control Plane Support (added in 0.1.8)
Recently in version `0.1.7` of `kube-vip` we added the functionality to use a Equinix Metal Elastic IP as the virtual IP fronting the Kubernetes Control plane cluster. In order to first get out virtual IP we will need to use our Equinix Metal account and create a EIP (either public or private). We will only need a single address so a `/32` will suffice, once this is created as part of a Equinix Metal project we can now apply this address to the servers that live in the same project.
In this example we've logged into the UI can created a new EIP of `147.75.1.2`, and we've deployed three small server instances with Ubuntu.
The following new flags are used:
-`--metal` which enables the use of the Equinix Metal API
-`--metalKey` which is our API key
-`--metalProject`which is the name of our Equinix Metal project where our servers and EIP are located.
*Also* the `--arp` flag should NOT be used as it wont work within the Equinix Metal network.
We've designed `kube-vip` to be as de-coupled or agnostic from other components that may exist within a Kubernetes cluster as possible. This has lead to `kube-vip` having a very simplistic but robust approach to advertising Kubernetes services to the outside world and marking these services as ready to use.
## Flow
This section details the flow of events in order for `kube-vip` to advertise a Kubernetes service:
1. An end user exposes a application through Kubernetes as a LoadBalancer => `kubectl expose deployment nginx-deployment --port=80 --type=LoadBalancer --name=nginx`
2. Within the Kubernetes cluster a service object is created with the `svc.Spec.Type = ServiceTypeLoadBalancer`
3. A controller (typically a Cloud Controller) has a loop that "watches" for services of the type `LoadBalancer`.
4. The controller now has the responsibility of providing an IP address for this service along with doing anything that is network specific for the environment where the cluster is running.
5. Once the controller has an IP address it will update the service `svc.Spec.LoadBalancerIP` with it's new IP address.
6. The `kube-vip` pods also implement a "watcher" for services that have a `svc.Spec.LoadBalancerIP` address attached.
7. When a new service appears `kube-vip` will start advertising this address to the wider network (through BGP/ARP) which will allow traffic to come into the cluster and hit the service network.
8. Finally `kube-vip` will update the service status so that the API reflects that this LoadBalancer is ready. This is done by updating the `svc.Status.LoadBalancer.Ingress` with the VIP address.
## CCM
We can see from the [flow](#Flow) above that `kube-vip` isn't coupled to anything other than the Kubernetes API, and will only act upon an existing Kubernetes primative (in this case the object of type `Service`). This makes it easy for existing CCMs to simply apply their logic to services of type LoadBalancer and leave `kube-vip` to take the next steps to advertise these load-balancers to the outside world.
## Using the Kube-vip Cloud Provider
The below instructions *should just work* on Kubernetes regardless of architecture (Linux Operating System is the only requirement) - you can quickly install the "latest" components:
Creating services of `type: LoadBalancer` in *any namespace* will now take addresses from the **global** cidr defined in the `configmap` unless a specific
To manage the IP address ranges for the load balancer instances the `kube-vip-cloud-provider` uses a `configmap` held in the `kube-system` namespace. IP address ranges can be configured using:
- IP address pools by CIDR
- IP ranges [start address - end address]
- Multiple pools by CIDR per namespace
- Multiple IP ranges per namespace (handles overlapping ranges)
- Setting of static addresses through --load-balancer-ip=x.x.x.x
To control which IP address range is used for which service the following rules are applied:
- Global address pools (`cidr-global` or `range-global`) are available for use by *any*`service` in *any*`namespace`
- Namespace specific address pools (`cidr-<namespace>` or `range-<namespace>`) are *only* available for use by `service` in the *specific*`namespace`
- Static IP addresses can be applied to a load balancer `service` using the `loadbalancerIP` setting, even outside of the assigned ranges
Example Configmap:
```
$ kubectl get configmap -n kube-system kubevip -o yaml
apiVersion: v1
kind: ConfigMap
metadata:
name: kubevip
namespace: kube-system
data:
cidr-default: 192.168.0.200/29 # CIDR-based IP range for use in the default namespace
range-development: 192.168.0.210-192.168.0.219 # Range-based IP range for use in the development namespace
cidr-finance: 192.168.0.220/29,192.168.0.230/29 # Multiple CIDR-based ranges for use in the finance namespace
cidr-global: 192.168.0.240/29 # CIDR-based range which can be used in any namespace
```
### Expose a service
We can now expose a service and once the cloud provider has provided an address `kube-vip` will start to advertise that address to the outside world as shown below!
With the latest release of `kube-vip` > 0.2.1, it is possible to use the local network DHCP server to provide `kube-vip` with a load-balancer address that can be used to access a
Kubernetes service on the network.
In order to do this we need to signify to `kube-vip` and the cloud-provider that we don't need one of their managed addresses. We do this by explicitly exposing a service on the
address `0.0.0.0`. When `kube-vip` sees a service on this address it will create a `macvlan` interface on the host and request a DHCP address, once this address is provided it will assign it as the VIP and update the Kubernetes service!
```
$ k expose deployment nginx-deployment --port=80 --type=LoadBalancer --name=nginx-dhcp --load-balancer-ip=0.0.0.0; k get svc
### Using UPNP to expose a service to the outside world
With the latest release of `kube-vip` > 0.2.1, it is possible to expose a load-balancer on a specific port and using UPNP (on a supported gateway) expose this service to the inte
rnet.
Most simple networks look something like the following:
Using UPNP we can create a matching port on the `<external network address>` allowing your service to be exposed to the internet.
#### Enable UPNP
Add the following to the `kube-vip` `env:` section, and the rest should be completely automated.
**Note** some environments may require (Unifi) will require `Secure mode` being `disabled` (this allows a host with a different address to register a port)
```
- name: enableUPNP
value: "true"
```
#### Exposing a service
To expose a port successfully we'll need to change the command slightly:
`--target-port=80` the port of the application in the pods (HTT/NGINX)
`--port=32380` the port the service will be exposed on (and what you should connect to in order to receive traffic from the service)
## Equinix Metal Overview (using the [Equinix Metal CCM](https://github.com/packethost/packet-ccm))
Below are two examples for running `type:LoadBalancer` services on worker nodes only and will create a daemonset that will run `kube-vip`.
**NOTE** This use-case requires the [Equinix Metal CCM](https://github.com/packethost/packet-ccm) to be installed and that the cluster/kubelet is configured to use an "external" cloud provider.
### Using Annotations
This is important as the CCM will apply the BGP configuration to the [node annotations](https://kubernetes.io/docs/concepts/overview/working-with-objects/annotations/) making it easy for `kube-vip` to find the networking configuration it needs to expose load balancer addresses. The `--annotations metal.equinix.com` will cause kube-vip to "watch" the annotations of the worker node that it is running on, once all of the configuarion has been applied by the CCM then the `kube-vip` pod is ready to advertise BGP addresses for the service.
```
kube-vip manifest daemonset \
--interface $INTERFACE \
--services \
--bgp \
--annotations metal.equinix.com \
--inCluster | k apply -f -
```
### Using the existing CCM secret
Alternatively it is possible to create a daemonset that will use the existing CCM secret to do an API lookup, this will allow for discovering the networking configuration needed to advertise loadbalancer addresses through BGP.
In Hybrid mode `kube-vip` will manage a virtual IP address that is passed through it's configuration for a Highly Available Kubernetes cluster, it will also "watch" services of `type:LoadBalancer` and once their `spec.LoadBalancerIP` is updated (typically by a cloud controller) it will advertise this address using BGP/ARP.
The "hybrid" mode is now the default mode in `kube-vip` from `0.2.3` onwards, and allows both modes to be enabled at the same time.
## Generating a Manifest
This section details creating a number of manifests for various use cases
### Set configuration details
`export VIP=192.168.0.40`
`export INTERFACE=<interface>`
### Configure to use a container runtime
The easiest method to generate a manifest is using the container itself, below will create an alias for different container runtimes.
#### containerd
`alias kube-vip="ctr run --rm --net-host docker.io/plndr/kube-vip:0.3.1 vip /kube-vip"`
#### Docker
`alias kube-vip="docker run --network host --rm plndr/kube-vip:0.3.1"`
### ARP
This configuration will create a manifest that starts `kube-vip` providing **controlplane** and **services** management, using **leaderElection**. When this instance is elected as the leader it will bind the `vip` to the specified `interface`, this is also the same for services of `type:LoadBalancer`.
`export INTERFACE=eth0`
```
kube-vip manifest pod \
--interface $INTERFACE \
--vip $VIP \
--controlplane \
--services \
--arp \
--leaderElection | tee /etc/kubernetes/manifests/kube-vip.yaml
```
### BGP
This configuration will create a manifest that will start `kube-vip` providing **controlplane** and **services** management. **Unlike** ARP, all nodes in the BGP configuration will advertise virtual IP addresses.
**Note** we bind the address to `lo` as we don't want multiple devices that have the same address on public interfaces. We can specify all the peers in a comma seperate list in the format of `address:AS:password:multihop`.
`export INTERFACE=lo`
```
kube-vip manifest pod \
--interface $INTERFACE \
--vip $VIP \
--controlplane \
--services \
--bgp \
--localAS 65000 \
--bgpRouterID 192.168.0.2 \
--bgppeers 192.168.0.10:65000::false,192.168.0.11:65000::false | tee /etc/kubernetes/manifests/kube-vip.yaml
```
### BGP with Equinix Metal
When deploying Kubernetes with Equinix Metal with the `--controlplane` functionality we need to pre-populate the BGP configuration in order for the control plane to be advertised and work in a HA scenario. Luckily Equinix Metal provides the capability to "look up" the configuration details (for BGP) that we need in order to advertise our virtual IP for HA functionality. We can either make use of the [Equinix Metal API](https://metal.equinix.com/developers/api/) or we can parse the [Equinix Metal Metadata service](https://metal.equinix.com/developers/docs/servers/metadata/).
**Note** If this cluster will be making use of Equinix Metal for `type:LoadBalancer` (by using the [Equinix Metal CCM](https://github.com/packethost/packet-ccm)) then we will need to ensure that nodes are set to use an external cloud-provider. Before doing a `kubeadm init|join` ensure the kubelet has the correct flags by using the following command `echo KUBELET_EXTRA_ARGS=\"--cloud-provider=external\" > /etc/default/kubelet`.
#### Creating a manifest using the API
We can enable `kube-vip` with the capability to discover the required configuration for BGP by passing the `--metal` flag and the API Key and our project ID.
```
kube-vip manifest pod \
--interface $INTERFACE\
--vip $VIP \
--controlplane \
--services \
--bgp \
--metal \
--metalKey xxxxxxx \
--metalProjectID xxxxx | tee /etc/kubernetes/manifests/kube-vip.yaml
```
#### Creating a manifest using the metadata
We can parse the metadata, *however* it requires that the tools `curl` and `jq` are installed.
Due to an oddity with `kubeadm` we can't have our `kube-vip` manifest present **before** joining our additional nodes. So on these control plane nodes we will add them first to the cluster.
```
sudo kubeadm join $VIP:6443 \
--token w5atsr.blahblahblah
--control-plane \
--certificate-key abc123
```
**Once**, joined these nodes can have the same command that we ran on the first node to populate the `/etc/kubernetes/manifests/` folder with the `kube-vip` manifest.
## Services
At this point your `kube-vip` static pods will be up and running and where used with the `--services` flag will also be watching for Kubernetes services that they can advertise. In order for `kube-vip` to advertise a service it needs a CCM or other controller to apply an IP address to the `spec.LoadBalancerIP`, which marks the loadbalancer as defined.
Kubernetes Virtual IP and Load-Balancer for both control plane and Kubernetes services
The idea behind `kube-vip` is a small self-contained Highly-Available option for all environments, especially:
- Bare-Metal
- On-Prem
- Edge (ARM / Raspberry PI)
- Virtualisation
- Pretty much anywhere else :)
## Features
Kube-Vip was originally created to provide a HA solution for the Kubernetes control plane, over time it has evolved to incorporate that same functionality into Kubernetes service type [load-balancers](https://kubernetes.io/docs/concepts/services-networking/service/#loadbalancer).
- VIP addresses can be both IPv4 or IPv6
- Control Plane with ARP (Layer 2) or BGP (Layer 3)
- Control Plane using either [leader election](https://godoc.org/k8s.io/client-go/tools/leaderelection) or [raft](https://en.wikipedia.org/wiki/Raft_(computer_science))
- Control Plane HA with kubeadm (static Pods)
- Control Plane HA with K3s/and others (daemonsets)
- Service LoadBalancer using [leader election](https://godoc.org/k8s.io/client-go/tools/leaderelection) for ARP (Layer 2)
- Service LoadBalancer using multiple nodes with BGP
- Service LoadBalancer address pools per namespace or global
- Service LoadBalancer address via (existing network DHCP)
- Service LoadBalancer address exposure to gateway via UPNP
- ... manifest generation, vendor API integrations and many nore...
## Why?
The "original" purpose of `kube-vip` was to simplify the building of HA Kubernetes clusters, which at this time can involve a few components and configurations that all need to be managed. This was blogged about in detail by [thebsdbox](https://twitter.com/thebsdbox/) here -> [https://thebsdbox.co.uk/2020/01/02/Designing-Building-HA-bare-metal-Kubernetes-cluster/#Networking-load-balancing](https://thebsdbox.co.uk/2020/01/02/Designing-Building-HA-bare-metal-Kubernetes-cluster/#Networking-load-balancing). As the project evolved it now can use those same technologies to provide load-balancing capabilities within a Kubernetes Cluster.
## Architecture
The architecture for `kube-vip` (and associated kubernetes components) is covered in detail [here](/architecture/)
## Installation
There are two main routes for deploying `kube-vip`, either through a [static pod](https://kubernetes.io/docs/tasks/configure-pod-container/static-pod/) when bringing up a Kubernetes cluster with [kubeadm](https://kubernetes.io/docs/setup/production-environment/tools/kubeadm/create-cluster-kubeadm/) or as a [daemon set](https://kubernetes.io/docs/concepts/workloads/controllers/daemonset/) (typically with distributions like [k3s](https://k3s.io)).
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.40 |
| controlPlane01 | 10.0.0.41 |
| controlPlane02 | 10.0.0.42 |
| controlPlane03 | 10.0.0.43 |
| worker01 | 10.0.0.44 |
All nodes are running Ubuntu 20.04, Docker CE and will use Kubernetes 1.21.0, we only have one worker as we're going to use our controlPlanes in "hybrid" mode.
- [Static Pod](/install_static)
- [Daemon Set](/install_daemonset)
## Usage
- [On-Prem with the kube-vip cloud controller](/usage/on-prem)
- [KIND](/usage/kind)
- [Equinix Metal](/usage/EquinixMetal)
- [k3s](/usage/k3s)
## Flags/Environment Variables
- [Flags and Environment variables](/flags/)
## Links
- The Kube-Vip Cloud Provider Repository -> [https://github.com/kube-vip/kube-vip-cloud-provider](https://github.com/kube-vip/kube-vip-cloud-provider)
- The Kube-Vip Repository -> [https://github.com/kube-vip/kube-vip](https://github.com/kube-vip/kube-vip)
Other Kubernetes distributions can bring up a Kubernetes cluster, without depending on a VIP (BUT they are configured to support one). A prime example of this would be k3s, that can be configured to start and also sign the certificates to allow incoming traffic to a virtual IP. Given we don't need the VIP to exist **before** the cluster, we can bring up the k3s node(s) and then add `kube-vip` as a daemonset for all control plane nodes.
If the Kubernetes installer allows for adding a Virtual IP as an additional [SAN](https://en.wikipedia.org/wiki/Subject_Alternative_Name) to the API server certificate then we can apply `kube-vip` to the cluster once the first node has been brought up.
## Kube-Vip as **HA**, **Load-Balancer** or both ` ¯\_(ツ)_/¯`
When generating a manifest for `kube-vip` we will pass in the flags `--controlplane` / `--services` these will enable the various types of functionality within `kube-vip`.
With both enabled `kube-vip` will manage a virtual IP address that is passed through it's configuration for a Highly Available Kubernetes cluster, it will also "watch" services of `type:LoadBalancer` and once their `spec.LoadBalancerIP` is updated (typically by a cloud controller) it will advertise this address using BGP/ARP.
**Note about Daemonsets**
Unlike generating the static manifest there are a few more things that may need configuring, this page will cover most scenarios.
## Create the RBAC settings
As a daemonSet runs within the Kubernetes cluster it needs the correct access to be able to watch Kubernetes services and other objects. In order to do this we create a User, Role, and a binding.. we can apply this with the command:
This section only covers generating a simple *BGP* configuration, as the main focus is will be on additional changes to the manifest. For more examples we can look at [here](/hybrid/static/).
**Note:** Pay attention if using the "static" examples, as the `manifest` subcommand should use `daemonset` and NOT `pod`.
### Set configuration details
`export VIP=192.168.0.40`
`export INTERFACE=<interface>`
### Configure to use a container runtime
The easiest method to generate a manifest is using the container itself, below will create an alias for different container runtimes.
#### containerd
`alias kube-vip="ctr run --rm --net-host docker.io/plndr/kube-vip:0.3.1 vip"`
#### Docker
`alias kube-vip="docker run --network host --rm plndr/kube-vip:0.3.1"`
### BGP Example
This configuration will create a manifest that will start `kube-vip` providing **controlplane** and **services** management. **Unlike** ARP, all nodes in the BGP configuration will advertise virtual IP addresses.
**Note** we bind the address to `lo` as we don't want multiple devices that have the same address on public interfaces. We can specify all the peers in a comma seperate list in the format of `address:AS:password:multihop`.
**Note 2** we pass the `--inCluster` flag as this is running as a daemonSet within the Kubernetes cluster and therefore will have access to the token inside the running pod.
**Note 2** we pass the `--taint` flag as we're deploying `kube-vip` as both a daemonset and as advertising controlplane, we want to taint this daemonset to only run on the worker nodes.
The routerID needs to be unique on each node that participates in BGP advertisements. In order to do this we can modify the manifest so that when `kube-vip` starts it will look up its local address and use that as the routerID.
```
- name: bgp_routerinterface
value: "ens160"
```
This will instruct each instance of `kube-vip` as part of the daemonset to look up the IP address on that interface and use it as the routerID.
### Manifest Overview
-`nodeSelector` - Ensures that this particular daemonset only runs on control plane nodes
-`serviceAccountName: kube-vip` - this specifies the user in the `rbac` that will give us the permissions to get/update services.
-`hostNetwork: true` - This pod will need to modify interfaces (for VIPs)
-`env {...}` - We pass the configuration into the kube-vip pod through environment variables.
Static pods are a Kubernetes pod that is ran by the `kubelet` on a single node, and is **not** managed by the Kubernetes cluster itself. This means that whilst the pod can appear within Kubernetes it can't make use of a variety of kubernetes functionality (such as the kubernetes token or `configMaps`). The static pod approach is primarily required for [kubeadm](https://kubernetes.io/docs/setup/production-environment/tools/kubeadm/create-cluster-kubeadm/), this is due to the sequence of actions performed by `kubeadm`. Ideally we want `kube-vip` to be part of the kubernetes cluster, for various bits of functionality we also need `kube-vip` to provide a HA virtual IP as part of the installation.
The sequence of events for this to work follows:
1. Generate a `kube-vip` manifest in the static pods manifest folder
2. Run `kubeadm init`, this generates the manifests for the control plane and wait to connect to the VIP
3. The `kubelet` will parse and execute all manifest, including the `kube-vip` manifest
4.`kube-vip` starts and advertises our VIP
5. The `kubeadm init` finishes succesfully.
## Kube-Vip as **HA**, **Load-Balancer** or both ` ¯\_(ツ)_/¯`
When generating a manifest for `kube-vip` we will pass in the flags `--controlplane` / `--services` these will enable the various types of functionality within `kube-vip`.
With both enabled `kube-vip` will manage a virtual IP address that is passed through it's configuration for a Highly Available Kubernetes cluster, it will also "watch" services of `type:LoadBalancer` and once their `spec.LoadBalancerIP` is updated (typically by a cloud controller) it will advertise this address using BGP/ARP.
## Generating a Manifest
This section details creating a number of manifests for various use cases
### Set configuration details
`export VIP=192.168.0.40`
`export INTERFACE=<interface>`
## Configure to use a container runtime
The easiest method to generate a manifest is using the container itself, below will create an alias for different container runtimes.
### containerd
`alias kube-vip="ctr run --rm --net-host docker.io/plndr/kube-vip:0.3.1 vip /kube-vip"`
### Docker
`alias kube-vip="docker run --network host --rm plndr/kube-vip:0.3.1"`
## ARP
This configuration will create a manifest that starts `kube-vip` providing **controlplane** and **services** management, using **leaderElection**. When this instance is elected as the leader it will bind the `vip` to the specified `interface`, this is also the same for services of `type:LoadBalancer`.
`export INTERFACE=eth0`
```
kube-vip manifest pod \
--interface $INTERFACE \
--vip $VIP \
--controlplane \
--services \
--arp \
--leaderElection | tee /etc/kubernetes/manifests/kube-vip.yaml
```
## BGP
This configuration will create a manifest that will start `kube-vip` providing **controlplane** and **services** management. **Unlike** ARP, all nodes in the BGP configuration will advertise virtual IP addresses.
**Note** we bind the address to `lo` as we don't want multiple devices that have the same address on public interfaces. We can specify all the peers in a comma seperate list in the format of `address:AS:password:multihop`.
`export INTERFACE=lo`
```
kube-vip manifest pod \
--interface $INTERFACE \
--vip $VIP \
--controlplane \
--services \
--bgp \
--localAS 65000 \
--bgpRouterID 192.168.0.2 \
--bgppeers 192.168.0.10:65000::false,192.168.0.11:65000::false | tee /etc/kubernetes/manifests/kube-vip.yaml
To deploy the [latest] then `kubectl apply -f https://kube-vip.io/manifests/kube-vip.yaml`, specific versions should be found in the repository as detailed below:
From the GitHub repository [https://github.com/kube-vip/kube-vip/tree/master/example/deploy](https://github.com/kube-vip/kube-vip/tree/master/example/deploy) find the version of the `kube-vip` to deploy (although typically the highest version number will provider more functionality/stability). The [raw] option in Github will provide the url that can be applied directly with a `kubectl apply -f <url>`.
The following output should appear when the manifest is applied:
```
serviceaccount/vip created
role.rbac.authorization.k8s.io/vip-role created
rolebinding.rbac.authorization.k8s.io/vip-role-bind created
deployment.apps/kube-vip-cluster created
```
*NOTE* The manifest for the `kube-vip` deployment has rules to ensure affinity (pods are always distributed to different nodes for HA). By default the replicas are set to `3` in the event you have less than `3` worker nodes then those replicas will sit as `pending`. This in itself isn't an issue, it means when new workers are added then they will be scheduled. *However*, tooling such as `kapps` will inspect the manifest before it's applied an error because of issues such as this.
### Editing `kube-vip` configuration
Either download and edit the manifest locally or apply as above and edit the deployment with `kubectl edit deploy/kube-vip-cluster` (change namespace where appropriate `-n`)
```
- name: vip_interface
value: ens192
- name: vip_configmap
value: plndr
- name: vip_arp
value: "true"
- name: vip_loglevel
value: "5"
```
-`vip_interface` - defines the interface that the VIP will bind to
-`vip_configmap` - defines the `configmap` that `kube-vip` will watch for service configuration
-`vip_arp` - determines if ARP broadcasts are enabled
-`vip_loglevel` - determines the verbosity of logging
## Using other namespaces
In this example we'll deploy and load-balance within the namespace `plunder`
### Create the namespace
`kubectl create namespace plunder`
### Add a network range/cidr for this namespace
`kubectl edit -n kube-system configmap/plndr`
We will add the range 192.168.0.210/29 for the namespace plunder underneath the existing range for the namespace default:
```
apiVersion: v1
data:
cidr-default: 192.168.0.200/29
cidr-global: 192.168.0.210/29
cidr-plunder: 192.168.0.220/29
<...>
```
### Deploy `kube-vip` in the namespace **plunder**
In the same way we deployed `kube-vip` into the default namespace we can deploy the same manifest into a different namespace using `-n namespace` e.g.
**Note** change the version of manifest when actually deploying!
This example will deploy into the namespace `plunder` as mention in the [Using other namespaces](Using other namespaces) example. Remove the `-n plunder` to deploy within the `default` namespace.
With the latest release of `kube-vip` > 0.2.1, it is possible to use the local network DHCP server to provide `kube-vip` with a load-balancer address that can be used to access a Kubernetes service on the network.
In order to do this we need to signify to `kube-vip` and the cloud-provider that we don't need one of their managed addresses. We do this by explicitly exposing a service on the address `0.0.0.0`. When `kube-vip` sees a service on this address it will create a `macvlan` interface on the host and request a DHCP address, once this address is provided it will assign it as the VIP and update the Kubernetes service!
```
$ k expose deployment nginx-deployment --port=80 --type=LoadBalancer --name=nginx-dhcp --load-balancer-ip=0.0.0.0; k get svc
## Using UPNP to expose a service to the outside world
With the latest release of `kube-vip` > 0.2.1, it is possible to expose a load-balancer on a specific port and using UPNP (on a supported gateway) expose this service to the internet.
Most simple networks look something like the following:
Using UPNP we can create a matching port on the `<external network address>` allowing your service to be exposed to the internet.
### Enable UPNP
Add the following to the `kube-vip``env:` section, and the rest should be completely automated.
**Note** some environments may require (Unifi) will require `Secure mode` being `disabled` (this allows a host with a different address to register a port)
```
- name: enableUPNP
value: "true"
```
### Exposing a service
To expose a port successfully we'll need to change the command slightly:
`--target-port=80` the port of the application in the pods (HTT/NGINX)
`--port=32380` the port the service will be exposed on (and what you should connect to in order to receive traffic from the service)
To deploy the [latest] then `kubectl apply -f https://kube-vip.io/manifests/kube-vip.yaml`, specific versions should be found in the repository as detailed below:
From the GitHub repository [https://github.com/kube-vip/kube-vip/tree/master/example/deploy](https://github.com/kube-vip/kube-vip/tree/master/example/deploy) find the version of the `kube-vip` to deploy (although typically the highest version number will provider more functionality/stability). The [raw] option in Github will provide the url that can be applied directly with a `kubectl apply -f <url>`.
The following output should appear when the manifest is applied:
```
serviceaccount/vip created
role.rbac.authorization.k8s.io/vip-role created
rolebinding.rbac.authorization.k8s.io/vip-role-bind created
deployment.apps/kube-vip-cluster created
```
*NOTE* The manifest for the `kube-vip` deployment has rules to ensure affinity (pods are always distributed to different nodes for HA). By default the replicas are set to `3` in the event you have less than `3` worker nodes then those replicas will sit as `pending`. This in itself isn't an issue, it means when new workers are added then they will be scheduled. *However*, tooling such as `kapps` will inspect the manifest before it's applied an error because of issues such as this.
### Editing `kube-vip` configuration
Either download and edit the manifest locally or apply as above and edit the deployment with `kubectl edit deploy/kube-vip-cluster` (change namespace where appropriate `-n`)
Ensure the `vip_arp` isn't enabled as ARP and BGP can't be used at the same time (today), also that the `vip_interface` is set to localhost (`lo`).
```
- name: vip_interface
value: "lo"
- name: vip_configmap
value: "plndr"
- name: bgp_enable
value: "true"
- name: vip_loglevel
value: "5"
```
### BGP Specific configuration
Additionally for BGP we'll need some configuration details, your local friendly network admin should be able to help here:
```
- name: bgp_routerid
value: "192.168.0.45"
- name: bgp_as
value: "65000"
- name: bgp_peeraddress
value: "10.0.0.1"
- name: bgp_peeras
value: "65522"
```
### BGP on Packet
If you're lucky enough to be running services on Packet then The above BGP information can be found from the API, instead of specifying the above we need to use the following:
```
- name: vip_packet
value: "true"
- name: vip_packetproject
value: "My Project"
- name: PACKET_AUTH_TOKEN
value: "XXYZZYVVY"
```
With the above configuration in place, all `kube-vip` pods will start in active mode and when a service is exposed then all nodes will advertise the VIP to the routers.
## Expose a service
Given that `kube-vip` doesn't know your network (at this point) ask your local friendly network OPs for an address you can advertise. That is the address you can expose to the outside world as shown below!
Creating services of `type: LoadBalancer` in the default namespace will now take addresses from the **global** cidr defined in the `configmap`.
**Additional namespaces**
Edit the `configmap` and add in the cidr ranges for those namespaces, the key in the cidr should be `cidr-<namespace>`, then ensure that `kube-vip` is deployed into that namespace with the above `apply` command with the `-n namespace` flag.
## The Detailed guide
### Deploy the `plndr-cloud-provider`
To deploy the [latest] then `kubectl apply -f https://kube-vip.io/manifests/controller.yaml`, specific versions should be found in the repository as detailed below:
From the GitHub repository [https://github.com/kube-vip/plndr-cloud-provider/tree/master/example/pod](https://github.com/kube-vip/plndr-cloud-provider/tree/master/example/pod), find the version of the plunder cloud provider manifest (although typically the highest version number will provider more functionality/stability). The [raw] option in Github will provide the url that can be applied directly with a `kubectl apply -f <url>`.
The following output should appear when the manifest is applied:
```
serviceaccount/plunder-cloud-controller created
clusterrole.rbac.authorization.k8s.io/system:plunder-cloud-controller-role created
clusterrolebinding.rbac.authorization.k8s.io/system:plunder-cloud-controller-binding created
pod/plndr-cloud-provider created
```
We can validate the cloud-provider by examining the pods:
The `configmap` details a CIDR range *per* namespace, however as of (`kube-vip 0.2.1` and `plnder-cloud-provider 0.1.4`), there is now the option of having a **global** CIDR range (`cidr-global)`.
To manage the ranges for the load-balancer instances, the `plndr-cloud-provider` has a `configmap` held in the `kube-system` namespace. The structure for the key/values within the `configmap` should be that the key is in the format `cidr-<namespace>` and the value should be the cidr range.
Example Configmap:
```
apiVersion: v1
kind: ConfigMap
metadata:
name: plndr
namespace: kube-system
data:
cidr-default: 192.168.0.200/29
cidr-global: 192.168.0.210/29
```
### Deploying `kube-vip`
To use `kube-vip` in Layer2/ARP the follow this [guide](/kubernetes/arp/)
To use `kube-vip` in Layer3/BGP the follow this [guide](/kubernetes/bgp/)
# Equinix Metal Overview (using the [Equinix Metal CCM](https://github.com/packethost/packet-ccm))
## BGP with Equinix Metal
When deploying Kubernetes with Equinix Metal with the `--controlplane` functionality we need to pre-populate the BGP configuration in order for the control plane to be advertised and work in a HA scenario. Luckily Equinix Metal provides the capability to "look up" the configuration details (for BGP) that we need in order to advertise our virtual IP for HA functionality. We can either make use of the [Equinix Metal API](https://metal.equinix.com/developers/api/) or we can parse the [Equinix Metal Metadata service](https://metal.equinix.com/developers/docs/servers/metadata/).
**Note** If this cluster will be making use of Equinix Metal for `type:LoadBalancer` (by using the [Equinix Metal CCM](https://github.com/packethost/packet-ccm)) then we will need to ensure that nodes are set to use an external cloud-provider. Before doing a `kubeadm init|join` ensure the kubelet has the correct flags by using the following command `echo KUBELET_EXTRA_ARGS=\"--cloud-provider=external\" > /etc/default/kubelet`.
## Creating HA clusters in Equinix Metal
### Creating a manifest using the API
We can enable `kube-vip` with the capability to discover the required configuration for BGP by passing the `--metal` flag and the API Key and our project ID.
```
kube-vip manifest pod \
--interface $INTERFACE\
--vip $VIP \
--controlplane \
--services \
--bgp \
--metal \
--metalKey xxxxxxx \
--metalProjectID xxxxx | tee /etc/kubernetes/manifests/kube-vip.yaml
```
### Creating a manifest using the metadata
We can parse the metadata, *however* it requires that the tools `curl` and `jq` are installed.
Below are two examples for running `type:LoadBalancer` services on worker nodes only and will create a daemonset that will run `kube-vip`.
**NOTE** This use-case requires the [Equinix Metal CCM](https://github.com/packethost/packet-ccm) to be installed and that the cluster/kubelet is configured to use an "external" cloud provider.
### Using Annotations
This is important as the CCM will apply the BGP configuration to the [node annotations](https://kubernetes.io/docs/concepts/overview/working-with-objects/annotations/) making it easy for `kube-vip` to find the networking configuration it needs to expose load balancer addresses. The `--annotations metal.equinix.com` will cause kube-vip to "watch" the annotations of the worker node that it is running on, once all of the configuarion has been applied by the CCM then the `kube-vip` pod is ready to advertise BGP addresses for the service.
```
kube-vip manifest daemonset \
--interface $INTERFACE \
--services \
--bgp \
--annotations metal.equinix.com \
--inCluster | k apply -f -
```
### Using the existing CCM secret
Alternatively it is possible to create a daemonset that will use the existing CCM secret to do an API lookup, this will allow for discovering the networking configuration needed to advertise loadbalancer addresses through BGP.
If `kube-vip` has been sat waiting for a long time then you may need to investigate that the annotations have been applied correctly by doing running the `describe` on the node:
If there are errors regarding `169.254.255.1` or `169.254.255.2` in the `kube-vip` logs then the routes to the ToR switches that provide BGP peering may by missing from the nodes. They can be replaced with the below command:
## Optional Tidy environment (best if something was running before)
```
rm -rf /var/lib/rancher /etc/rancher ~/.kube/*; \
ip addr flush dev lo; \
ip addr add 127.0.0.1/8 dev lo;
```
## Step 1: Create Manifests folder
This is required, this folder will contain all of the generated manifests that `k3s` will execute as it starts. We will create it before `k3s` and place our `kube-vip` manifests within it.
```
mkdir -p /var/lib/rancher/k3s/server/manifests/
```
## Step 2: Get rbac for `Kube-Vip`
As `kube-vip` runs inside of the Kubernetes cluster, we will need to ensure that the required permissions exist.
## Step 3: Generate kube-vip (A VIP address for the network will be required)
Configure your virtual IP (for the control plane) and interface that will expose this VIP first.
```
export VIP=x.x.x.x
export INTERFACE=ethx
```
Modify the `VIP` and `INTERFACE` to match the floating IP address you'd like to use and the interface it should bind to.
To generate the manifest we have two options! We can generate the manifest from [kube-vip.io](kube-vip.io) or use a kube-vip image to generate the manifest!
## Step 3.1: Generate from kube-vip.io
```
curl -sL kube-vip.io/k3s | vipAddress=$VIP vipInterface=$INTERFACE sh | sudo tee /var/lib/rancher/k3s/server/manifests/vip.yaml
```
## Step 3.2 Genereate from container image
### containerd
`alias kube-vip="ctr run --rm --net-host docker.io/plndr/kube-vip:0.3.1 vip /kube-vip"`
### Docker
`alias kube-vip="docker run --network host --rm plndr/kube-vip:0.3.1"`
The documentation for KIND is fantastic and it's quickstart guide will have you up and running in no time -> [https://kind.sigs.k8s.io/docs/user/quick-start/](https://kind.sigs.k8s.io/docs/user/quick-start/)
## Find Address Pool for Kube-Vip
We will need to find addresses that can be used by Kube-Vip:
```
docker network inspect kind -f '{{ range $i, $a := .IPAM.Config }}{{ println .Subnet }}{{ end }}'
```
This will return a cidr range such as `172.18.0.0/16` and from here we can select a range.
We've designed `kube-vip` to be as de-coupled or agnostic from other components that may exist within a Kubernetes cluster as possible. This has lead to `kube-vip` having a very simplistic but robust approach to advertising Kubernetes services to the outside world and marking these services as ready to use.
## Flow
This section details the flow of events in order for `kube-vip` to advertise a Kubernetes service:
1. An end user exposes a application through Kubernetes as a LoadBalancer => `kubectl expose deployment nginx-deployment --port=80 --type=LoadBalancer --name=nginx`
2. Within the Kubernetes cluster a service object is created with the `svc.Spec.Type = ServiceTypeLoadBalancer`
3. A controller (typically a Cloud Controller) has a loop that "watches" for services of the type `LoadBalancer`.
4. The controller now has the responsibility of providing an IP address for this service along with doing anything that is network specific for the environment where the cluster is running.
5. Once the controller has an IP address it will update the service `svc.Spec.LoadBalancerIP` with it's new IP address.
6. The `kube-vip` pods also implement a "watcher" for services that have a `svc.Spec.LoadBalancerIP` address attached.
7. When a new service appears `kube-vip` will start advertising this address to the wider network (through BGP/ARP) which will allow traffic to come into the cluster and hit the service network.
8. Finally `kube-vip` will update the service status so that the API reflects that this LoadBalancer is ready. This is done by updating the `svc.Status.LoadBalancer.Ingress` with the VIP address.
## CCM
We can see from the [flow](#Flow) above that `kube-vip` isn't coupled to anything other than the Kubernetes API, and will only act upon an existing Kubernetes primative (in this case the object of type `Service`). This makes it easy for existing CCMs to simply apply their logic to services of type LoadBalancer and leave `kube-vip` to take the next steps to advertise these load-balancers to the outside world.
## Using the Kube-vip Cloud Provider
The below instructions *should just work* on Kubernetes regardless of architecture (Linux Operating System is the only requirement) - you can quickly install the "latest" components:
Creating services of `type: LoadBalancer` in *any namespace* will now take addresses from the **global** cidr defined in the `configmap` unless a specific
To manage the IP address ranges for the load balancer instances the `kube-vip-cloud-provider` uses a `configmap` held in the `kube-system` namespace. IP address ranges can be configured using:
- IP address pools by CIDR
- IP ranges [start address - end address]
- Multiple pools by CIDR per namespace
- Multiple IP ranges per namespace (handles overlapping ranges)
- Setting of static addresses through --load-balancer-ip=x.x.x.x
To control which IP address range is used for which service the following rules are applied:
- Global address pools (`cidr-global` or `range-global`) are available for use by *any*`service` in *any*`namespace`
- Namespace specific address pools (`cidr-<namespace>` or `range-<namespace>`) are *only* available for use by `service` in the *specific*`namespace`
- Static IP addresses can be applied to a load balancer `service` using the `loadbalancerIP` setting, even outside of the assigned ranges
Example Configmap:
```
$ kubectl get configmap -n kube-system kubevip -o yaml
apiVersion: v1
kind: ConfigMap
metadata:
name: kubevip
namespace: kube-system
data:
cidr-default: 192.168.0.200/29 # CIDR-based IP range for use in the default namespace
range-development: 192.168.0.210-192.168.0.219 # Range-based IP range for use in the development namespace
cidr-finance: 192.168.0.220/29,192.168.0.230/29 # Multiple CIDR-based ranges for use in the finance namespace
cidr-global: 192.168.0.240/29 # CIDR-based range which can be used in any namespace
```
### Expose a service
We can now expose a service and once the cloud provider has provided an address `kube-vip` will start to advertise that address to the outside world as shown below!
With the latest release of `kube-vip` > 0.2.1, it is possible to use the local network DHCP server to provide `kube-vip` with a load-balancer address that can be used to access a
Kubernetes service on the network.
In order to do this we need to signify to `kube-vip` and the cloud-provider that we don't need one of their managed addresses. We do this by explicitly exposing a service on the
address `0.0.0.0`. When `kube-vip` sees a service on this address it will create a `macvlan` interface on the host and request a DHCP address, once this address is provided it will assign it as the VIP and update the Kubernetes service!
```
$ k expose deployment nginx-deployment --port=80 --type=LoadBalancer --name=nginx-dhcp --load-balancer-ip=0.0.0.0; k get svc
### Using UPNP to expose a service to the outside world
With the latest release of `kube-vip` > 0.2.1, it is possible to expose a load-balancer on a specific port and using UPNP (on a supported gateway) expose this service to the inte
rnet.
Most simple networks look something like the following:
Using UPNP we can create a matching port on the `<external network address>` allowing your service to be exposed to the internet.
#### Enable UPNP
Add the following to the `kube-vip` `env:` section, and the rest should be completely automated.
**Note** some environments may require (Unifi) will require `Secure mode` being `disabled` (this allows a host with a different address to register a port)
```
- name: enableUPNP
value: "true"
```
#### Exposing a service
To expose a port successfully we'll need to change the command slightly:
`--target-port=80` the port of the application in the pods (HTT/NGINX)
`--port=32380` the port the service will be exposed on (and what you should connect to in order to receive traffic from the service)
# Load Balancing a Kubernetes Cluster (Control-Plane)
This document covers all of the details for using `kube-vip` to build a HA Kubernetes cluster
`tl;dr version`
- Generate/modify first node `kube-vip` config/manifest
-`init` first node
-`join` remaining nodes
- Add remaining config/manifests
## Infrastructure architecture
The infrastructure for our example HA Kubernetes cluster is as follows:
| Node | Address |
|----------------|------------|
| VIP | 10.0.0.75 |
| controlPlane01 | 10.0.0.70 |
| controlPlane02 | 10.0.0.71 |
| controlPlane03 | 10.0.0.72 |
All nodes are running Ubuntu 18.04, Docker CE and will use Kubernetes 1.17.0.
### Generate the `kube-vip` configuration
Make sure that the config directory exists: `sudo mkdir -p /etc/kube-vip/`, this directory can be any directory however the `hostPath` in the manifest will need modifying to point to the correct path.
```
sudo docker run -it --rm plndr/kube-vip:0.1.5 sample config | sudo tee /etc/kube-vip/config.yaml
```
### Modify the configuration
**Cluster Configuration**
Modify the `remotePeers` to point to the correct addresses of the other two nodes, ensure that their `id` is unique otherwise this will confuse the raft algorithm. The `localPeer` should be the configuration of the current node (`controlPlane01`), which is where this instance of the cluster will run.
As this node will be the first node, it will need to elect itself leader as until this occurs the VIP won’t be activated!
`startAsLeader: true`
**VIP Config**
We will need to set our VIP address to `192.168.0.75` and to ensure all hosts are updated when the VIP moves we will enable ARP broadcasts `gratuitousARP: true`
**Load Balancer**
We will configure the load balancer to sit on the standard API-Server port `6443` and we will configure the backends to point to the API-servers that will be configured to run on port `6444`. Also for the Kubernetes Control Plane we will configure the load balancer to be of `type: tcp`.
We can also use `6443` for both the VIP and the API-Servers, in order to do this we need to specify that the api-server is bound to it's local IP. To do this we use the `--apiserver-advertise-address` flag as part of the `init`, this means that we can then bind the same port to the VIP and we wont have a port conflict.
To generate the basic Kubernetes static pod `yaml` configuration:
Make sure that the manifest directory exists: `sudo mkdir -p /etc/kubernetes/manifests/`
```
sudo docker run -it --rm plndr/kube-vip:0.1.5 sample manifest | sudo tee /etc/kubernetes/manifests/kube-vip.yaml
```
Ensure that `image: plndr/kube-vip:<x>` is modified to point to a specific version (`0.1.5` at the time of writing), refer to [docker hub](https://hub.docker.com/r/plndr/kube-vip/tags) for details. Also ensure that the `hostPath` points to the correct `kube-vip` configuration, if it isn’t the above path.
The **vip** is set to `192.168.0.75` and this first node will elect itself as leader, and as part of the `kubeadm init` it will use the VIP in order to speak back to the initialising api-server.
We first will need to create the `kube-vip` configuration that resides in `/etc/kube-vip/config.yaml` or we can regenerate it from scratch using the above example. Ensure that the configuration is almost identical with the `localPeer` and `remotePeers` sections are updated for each node. Finally, ensure that the remaining nodes will behave as standard cluster nodes by setting `startAsLeader: false`.
At this point **DON’T** generate the manifests, this is due to some bizarre `kubeadm/kubelet` behaviour.
```
kubeadm join 192.168.0.75:6443 --token <tkn> \
--discovery-token-ca-cert-hash sha256:<hash> \
--control-plane --certificate-key <key>
```
**After** this node has been added to the cluster, we can add the manifest to also add this node as a `kube-vip` member. (Adding the manifest afterwards doesn’t interfere with `kubeadm`).
```
sudo docker run -it --rm plndr/kube-vip:0.1.5 sample manifest | sudo tee /etc/kubernetes/manifests/kube-vip.yaml
```
Once this node is added we will be able to see that the `kube-vip` pod is up and running as expected:
```
user@controlPlane01:~$ kubectl get pods -A | grep vip
// if last event is known, but an event of another type arrived,
// send out the previous event
iflast!=nil&&last.Type!=tmp.Type{
o.output<-*last
}
// save current event as the last event
last=&tmp
// reset the ticker to wait for more events
t.Reset(debounceTime)
case<-t.C:
iflast!=nil{
// on tick, if we have an event, send it out
o.output<-*last
// if the event is of type 'Deleted', stop the debouncer for the object
iflast.Type==watch.Deleted{
o.stop()
}
// reset last known event, so it won't be send out twice
last=nil
}
}
}
}
func(o*object)stop(){
o.stopOnce.Do(func(){
ifo.onStop!=nil{
o.onStop()
}
close(o.stopChan)
})
}
Some files were not shown because too many files have changed in this diff
Show More
Reference in New Issue
Block a user
Blocking a user prevents them from interacting with repositories, such as opening or commenting on pull requests or issues. Learn more about blocking a user.



